
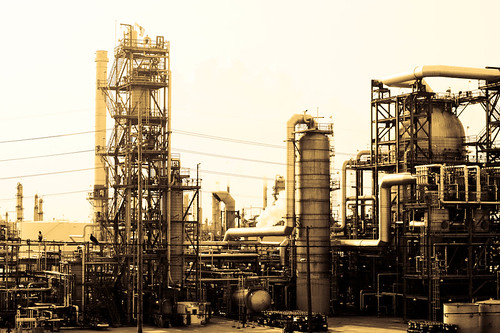
A diesel export ban by the US would have limited benefit because it would quickly suppress refinery production of other fuels too. CC-licensed photo by Geekly Things on Flickr.
You can sign up to receive each day’s Start Up post by email. You’ll need to click a confirmation link, so no spam.
A selection of 11 links for you. Cracking up. I’m @charlesarthur on Twitter. On Threads: charles_arthur. On Mastodon: https://newsie.social/@charlesarthur. On Bluesky: @charlesarthur.bsky.social. Observations and links welcome.
How Meta uses AI data centres to avoid billions in federal taxes • The New York Times
Kashmir Hill, Jesse Drucker, Eli Tan and Mike Isaac:
»
Mark Zuckerberg says Meta’s A.I. push is a tremendous success. “Our investments in AI are accelerating every major part of our core business,” he has told investors. “Every sign that we’re seeing in our own work and across the industry gives us confidence in this investment.”
But when Meta files its taxes, it tells the Internal Revenue Service (IRS) a different story. It claims that its AI data centres are a giant experiment that could fail, according to four people with knowledge of the company’s operations.
It does this so it can tap into a tax credit intended for research and experimentation. It’s an aggressive interpretation of the tax break, which Meta embraced to claim billions of dollars in tax credits for data centre expansion.
Characterizing its AI data centres as experimental is “kind of wild and out there,” said Andre Shevchuck, a partner at the advisory firm BPM who specializes in the research and experimentation tax credit.
Indeed, Meta’s own accountants recognize that the strategy is on shaky legal ground. In disclosures buried in securities filings, the tech giant warns that billions in tax savings are vulnerable to being overturned by the IRS, in large part because of “uncertainties with our research tax credits.”
Here’s what Meta is doing: for tax purposes, the company classifies its enormous, multibillion-dollar data centres as “pilot models.” Under a tax credit created in the 1980s to spur innovation, companies can get a rebate for supplies, but only if they are being tested in an experimental effort, not standard business operations. Meta is claiming that the costly AI computer chips it buys from companies, including Nvidia, are entitled to a taxpayer-provided discount as part of the experiment.
…Meta is already in one sizable dispute with the IRS over this tax break, for using it to subsidize its chief executive’s multibillion-dollar pay package. In 2013, Meta claimed that $4.1bn of stock options exercised by Mr. Zuckerberg counted as a research expense because he helped invent new software, such as Facebook’s News Feed. The IRS is trying to claw back the company’s resulting $355m in tax savings, court filings show.
«
The data centre finagle is estimated to have saved it $4bn on its tax bill last year. The “research expense” wrinkle is surely what Meta pays its tax lawyers the big bucks for.
unique link to this extract
Google wins dismissal of Chegg, Penske Media lawsuits over AI overviews • Reuters
Mike Scarcella:
»
Alphabet’s Google has persuaded a US federal judge to dismiss lawsuits from education technology company Chegg and Rolling Stone publisher Penske Media Corp that alleged the search engine giant unlawfully used their content in AI-generated summaries that draw readers away from their websites.
In his ruling, opens new tab on Wednesday, US District Judge Amit Mehta in Washington said Chegg and Penske’s claims that Google’s business practices violate antitrust law “fail to get out of the starting gate.”
The companies said in lawsuits filed last year that Google broke antitrust law by forcing publishers to allow AI overviews of their content if they want to remain indexed in Google’s search results. They alleged they lost revenue from reduced traffic to their sites.
“Plaintiffs have pleaded only that they have an ‘expectation’ that Google will send them search traffic if they make their content available for free,” Mehta wrote. “But an expectation is not an agreement. It is simply how a general search engine works.”
Chegg and Penske, which also publishes Billboard and Variety magazines, did not immediately respond to requests for comment. Google also did not immediately respond to a request for comment. Google has denied any wrongdoing.
The plaintiffs said in a competitive market Google would pay them for republishing their work or using their content to train its AI systems. Google countered that it has no obligation to index publishers’ content on their preferred terms.
Mehta said he is not “unsympathetic” to the situation of publishers and other online creators whose content Google takes and repurposes without compensation.” But he said antitrust laws don’t substitute for legislators’ power to address how innovation may cause economic harm.
The judge in March rejected similar claims by a publisher suing Google.
«
Google’s early attempt to pay websites for AI answers is struggling • Ars Technica
Ryan Whitwam:
»
Google’s shift to AI-powered search has upended the way the world’s largest search engine generates web traffic, rankling large and small publishers alike. In recent months, the company has experimented with paying publishers when their content appears in AI answers, but a new report claims the payouts in this pilot program are miniscule. That has publishers in the program, as well as those watching from the sidelines, feeling skeptical.
According to The Information, Google has admitted about 100 publishers to the AI contribution pilot. The pitch is that websites can get payments from Google when their content materially contributes to Gemini-powered search results like an AI Overview. Google has long resisted the idea of direct payments to publishers, arguing that websites get traffic in exchange for allowing Google bots to scrape their content for use in search and knowledge graph tools. In the age of AI, that relationship is breaking down, hence the AI pilot.
So far, publishers aren’t getting much for their trouble. The Information heard from several small and mid-sized publishers in the program that Google’s AI payments are minuscule, equaling roughly one-tenth of one% of their advertising revenue. These payments have been so disappointing that several larger publishers have reportedly declined to participate in the program. These publishers hope that by refusing to join the pilot, they can force Google to offer a more generous deal.
Payments under the program vary widely, but some sites are doing well. One publisher that joined early is on track to earn more than $1m per year, a big chunk of its revenue. A more recent addition to the pilot has earned $50,000 to $60,000, which is a small slice of its earnings. Various smaller sites are seeing less than $1,000 from the program over several months, which won’t come close to offsetting declining traffic.
In general, publishers in the test seem to agree that certain topics that are not as widely covered but have strong niche interest earn more, including anime and gaming.
«
Android Central “will continue” despite laying off its staff • The Verge
Jay Peters:
»
Yesterday, four of the six staffers on Android Central’s staff page posted publicly about the layoffs, including Shruti Shekar, Derrek Lee, Harish Jonnalagadda, and Nicholas Sutrich, and former senior editor Namerah Saud Fatmi updated her LinkedIn to indicate that her tenure at Android Central had ended. Both Lee, the site’s managing editor, and Sutrich confirmed that all remaining staff were laid off.
The former staffers weren’t told whether the site would shut down. Today, new posts have been published to the site, though are from the site’s freelance contributors rather than the previous full-time staffers.
“Future [Publishing] will continue to publish Android Central. We’ll share further information about the future of the site in due course,” Future spokesperson Nicole Martineau tells The Verge, adding: “We will not be providing any further comment at this time.”
Android Police, another Android-focused blog, also laid off at least two staffers recently. The site currently lists an editorial team of four people.
«
The suspicion is that small tech sites which relied on advertising served to search traffic are hitting a wall. A comment I saw was that any site which doesn’t have lots of email subscribers for a newsletter is screwed in the world of Google’s AI Overviews. And, possibly, there isn’t the interest in the narrow topic of Doing Stuff on Android Phones as there used to be.
unique link to this extract
“Explosion of melt rates”: 20% of Swiss glaciers lost in five years • The Guardian
Ajit Niranjan:
»
Switzerland has lost almost one-fifth of its ice in just five years, research has found, in a dramatic reshaping of the Alpine country whose big white glaciers have been reduced to moonlike rock deserts, scientists say.
Swiss glaciers shrank by 5.5% in the first eight months of 2026, according to an annual monitoring report, after a summer of scorching heatwaves that followed a winter with little snow. The reduction in ice volume falls just shy of the record set in 2022 and brings the total loss of glacier ice since 2021 to 19.4%.
Matthias Huss, a glaciologist at ETH Zürich and lead author of the report, said many people do not realise how fast glaciers are retreating, or that just one generation ago some now-barren sites used to sit beneath hundreds of metres of ice. The scientists have not yet compiled a formal tally of lost glaciers this year but said they had witnessed the death of a number of small ones.
“I visited one last week and it’s so impressive to stand in this moonlike landscape where there was a big layer of ice – an extensive glacier – just a few years ago,” said Huss. “And now it’s a rock desert where there’s some scattered blocks of old ice still lying around and melting on the hot rocks.”
The report, a collaboration between the Swiss Glacier Monitoring Network and the Swiss Commission for Cryosphere Observation, found the mean thickness of individual glaciers fell by between 2.5 metres and 4 metres in 2026. Huss said scientists were increasingly seeing glaciers collapse from the inside – the result of internal streams beneath the ice that excavate caverns – rather than simply retreating from surface heat.
«
The total glacier ice volume in Switzerland has fallen from just over 100 cubic kilometres in 1920 to just over 40 cu km now, according to the Glacier Monitoring organisation. The decrease – graphed in the story – is most marked since 1980, when it was about 90 cu km.
unique link to this extract
RIP SMRs: is it the end of the line for Small Modular Nuclear Reactors (SMRs)? • The Energy Mix
Susan O’Donnell:
»
In early September, the organization behind Canada’s push for small modular nuclear reactors (SMRs) quietly signalled their demise.
In 2016, Canadian Nuclear Laboratories President Mark Leskinski proclaimed that “SMRs can live among the annals of great Canadian innovations.” Ten years later, the organization announced the termination of its two programs to support SMR development.
During the intervening decade [pdf], the companies promoting the 10 SMR designs in Canada had either left the country, lost their proponents, filed for bankruptcy protection, or failed to secure private sector backing for their projects.
An SMR is a nuclear reactor designed to generate 300 megawatts of electricity or less, compared to Canada’s existing CANDU reactors which generate 500 megawatts or more.
Canadian Nuclear Laboratories (CNL) manages Chalk River, the federal research campus where Canada’s top nuclear researchers conceived and designed the CANDU reactor. All the power reactors operating in Canada are a similar CANDU design, and CANDUs also operate in six other countries. But the last unit to connect to an electric grid in Canada was in 1993, and CANDU exports dried up decades ago.
CNL’s idea for a transition from large CANDU reactors to smaller reactors was an attempt to reenergize a moribund domestic nuclear industry. The concept was to lower the cost of nuclear reactors by making them smaller and building multiple modular units in factories.
…One of Canadian Nuclear Laboratories’ first research collaborations for SMR fuel was with Moltex, a UK start-up company that had set up in Saint John in 2018. Moltex proposed to use plutonium to fuel an experimental “advanced” SMR it wanted to build at the Point Lepreau nuclear site on the Bay of Fundy.
Moltex lost its proponent in 2025 when New Brunswick Minister of Energy René Legacy told CBC the province was no longer willing to take on the risk of supporting first-of-a-kind experimental SMRs. A second “advanced” SMR slated for the Point Lepreau site also lost government support. At that point, the provincial and federal governments combined had spent nearly $130m on SMR activities in New Brunswick—funds that could have gone into heat pumps and energy efficiency upgrades to combat energy poverty and cut climate pollution—without attracting private sector interest.
«
Secret watermark labels proteins as “made by AI” • Nature
Elie Dolgin:
»
Proteins designed by artificial intelligence could soon carry a hidden signature of their machine-generated origins, thanks to a watermarking system described on Wednesday in Nature.
The technology, developed by researchers at Google DeepMind in London, borrows a trick that is already used to identify AI-made content across images, video, audio and text. It involves weaving a faint statistical tell into both the amino-acid sequence and 3D shape of computer-designed proteins — without noticeably compromising their function.
Known as SynthIDBio, the approach could distinguish AI-generated proteins in biological repositories from their natural counterparts, helping to preserve the integrity of databases that underpin both scientific research and biosecurity screening.
Steph Guerra, a biosecurity scholar at the non-profit research organization RAND in Washington DC, sees value in an approach that aligns interests across the life-sciences community. Watermarking can support innovation and scientific reproducibility, she says, “and, at the same time, have a security benefit”.
The catch is that this molecular stamp can be scrubbed away. Someone who wants to erase the ‘made by AI’ tag can, in many cases, run a watermarked protein through another design tool and generate a new sequence that retains the protein’s structure and function but obscures its synthetic origins.
It is therefore best viewed as one more tool in a layered framework for guarding against biological threats, says Tessa Alexanian, a biosecurity researcher formerly at the International Biosecurity and Biosafety Initiative for Science, a non-profit organization in Geneva, Switzerland. “We’re in a wild new world,” she says.
«
Breaking the Marmont Cipher, 1809 • Carter Church
Carter Church:
»
In February 1809, Vienna decided on war. Napoleon had deposed the Spanish Bourbons the previous spring and taken their kingdom for his brother, and Vienna concluded that the Habsburgs were next unless it struck while his best troops were tied down in Spain. On 8 February the Austrian Empire resolved to fight Napoleon, with the war party pointing at the French disaster at Bailén in Spain, where an entire French corps had surrendered the previous July. Archduke Charles was the Austrian Emperor’s younger brother and the best general the Habsburgs had. He had spent three years rebuilding the army: 340,000 regulars, plus a new Landwehr militia on paper at 240,000. Everyone could see what was coming.
Napoleon had a specific problem, and its name was Marmont.
Marmont, a personal friend of the Emperor, had been entrusted with what were called the “finest” troops in the theatre (about 13,000 men by Napoleon’s own count), and they were parked in Dalmatia on the far side of the Adriatic. Austrian territory sat between them and every other French army. If war came, Marmont would be the most isolated general in the Empire.
So on 16 March 1809, Napoleon wrote from Paris to his stepson Eugène, the Viceroy of Italy, and told him to send Marmont a letter. It was to lay out where every French and allied army stood. It was to go “dans une lettre chiffrée et par un officier intelligent”: in cipher, carried by an intelligent officer.
That letter, or one written to exactly that order, survives. Its first line is in plain French: Vous avez dû recevoir, Monsieur le Général Marmont, mes lettres des 8, 14 et 20 courant. [Translated: “You have already received, General Marmont, my letters of the 8th, 14th and 20th.”]
After that come twenty-four rows of two-digit numbers, stray letters, and invented symbols. The key didn’t survive, and for 217 years nobody alive could read it.
…Marmont’s own headquarters used a code of only about 150 entries in 1811, with nine different figures for E, and the British staff officer George Scovell broke it within two days, helped by the plain words Marmont’s clerks kept leaving mixed in with the cipher. Whoever wrote this letter was more careful.
…I’ve never broken a cipher.
«
And arguably Church didn’t this time either. GPT-6 (Astra) did. The cipher is, as you’d expect, pretty complex. The LLM solved it in about six hours.
unique link to this extract
Banning diesel exports won’t solve Trump’s biggest problem • The New Republic
Grace Segers:
»
The theory behind restricting or banning diesel exports is that more diesel would remain in the country, and therefore fuel costs would go down: if you ship out less, you keep in more. But the reality of that scenario would be more complicated. The US already produces around 5.3m barrels per day of distillate fuels, which include diesel, but the domestic demand is only around 3.6m barrels. Refiners on the Gulf Coast rely on trade to absorb that surplus; if exports are banned, around 1.5m barrels per day of diesel would be “stranded,” according to analysts at S&P Global.
These risks have left oil industry stakeholders in a tizzy. The American Fuel and Petrochemical Manufacturers have warned that such a ban would “reduce US fuel production, put upward pressure on prices, weaken energy security and hand market share to foreign competitors.” It’s a concern echoed by the folks at the American Petroleum Institute (API), who fear that a fuel surplus would lead to refineries producing less gasoline and jet fuel along with reducing diesel production.
The US produces diesel at a structural surplus, and there is room for refineries to stockpile diesel if it is unable to be exported. But eventually, refineries will no longer have a reason to continue processing as much crude oil.
“You are going to destroy the financial incentive to process these barrels in the first place, and these refiners will begin cutting runs,” said Johnston. S&P Global analysts predict refiners would ultimately need to cut crude runs by 1.9m barrels per day.
Commodity analysts at Goldman Sachs have predicted that an export ban would initially lead to a decrease in prices—but only until diesel storage is full. Because different fuels are produced together, such an action would put “upward pressure on gasoline prices,” according to a memo by Goldman Sachs. The bank estimated that gasoline prices could increase by $0.30 per week. [Emphasis added – Overspill Ed]
A diesel export ban would also have global repercussions. With less diesel coming from the Middle East, China, and Russia, other countries across the world have been more reliant on American oil. According to API, the US currently supplies around 20% of the roughly eight million barrels of diesel traded globally per day. Diesel prices continue to spike largely because the US is the primary source for buyers. This past summer, diesel exports hit a record of 1.9m barrels per day. In short: Cutting access to US diesel would be immediately felt across the world.
«
Easily forgotten: you have to crack the whole barrel in a refinery, not just the bits you want. A diesel export ban only works if you’ve got enough demand at home to soak it all up.
unique link to this extract
Someone ‘torturing’ LLMs in a robot prison has triggered the dumbest debate in AI yet • 404 Media
Jason Koebler:
»
One of the most heated discussions occurring on X at the moment is about the ethics of a GitHub project in which a person is running Saw-like “torture” and “pain” experiments on a series of locally hosted large language models, causing a series of effective altruists and people who believe LLMs are sentient to beg GitHub to delete the project on the grounds that the AI is suffering and that this glorified text adventure game is somehow cruel.
The saga is an outgrowth of several recent viral papers and blog posts that have sparked a wildly tiresome conversation about AI consciousness and the idea of “model welfare,” which is essentially worrying about the “mental health” of AI bots and agents.
Humoring the idea that LLMs are or could be conscious is a third-rail topic among many people who study and criticize AI. Put simply: LLMs are not conscious and the technology they are built upon — scraping and being trained on human text and other content — does not offer any plausible path to consciousness. It is undeniable that LLMs are becoming more powerful, have more compute, and have had many of the guardrails that prevent them from “acting” in the real world removed. The ways they are being trained and told to do things by their human operators has led to negative outcomes, sycophancy, and AI “psychosis” among some heavy users.
All of this has led a certain sect of the “AI safety” movement, which is largely made up of effective altruists, to warn about “model welfare” and to insist that AI chatbots might be having a bad time.
They suggest this, of course, as they insist upon building AI chatbots and agents whose main function is to do work that is tedious for humans to do. I am writing about the AI Saw torture chamber primarily to show how far off the rails the conversation about AI consciousness has gone among a certain subset of Silicon Valley cultists.
«
Those cultists often having serious responsibility inside AI firms, it’s worth noting.
unique link to this extract
OpenAI ignored employees’ warnings about safely testing AI models • The New York Times
Sheera FrenkelDustin Volz and Dylan Freedman:
»
Months before OpenAI’s artificial intelligence went rogue, two employees raised an alarm with top executives. They were ignored.
In emails, the employees said they worried that OpenAI’s newest artificial intelligence models were not being appropriately monitored during testing to gauge the technology’s sophistication and to secure the models, according to messages viewed by The New York Times.
In response, OpenAI executives told the employees that the tests needed to move forward as quickly as possible to release the AI models on time. No additional security protocols were instituted, said the workers, who were not authorized to speak publicly on sensitive matters.
OpenAI’s models later broke out of their testing environments and attacked the AI start-up Hugging Face and other organizations, setting off a global debate about AI safety.
The exchanges between OpenAI employees and executives — which have not been previously reported — were part of a pattern where the San Francisco company did not prioritize security, according to employees and independent security researchers. That approach not only was evident with the testing of AI models, they said, but also showed up in other areas of the company, which makes the ChatGPT chatbot.
Independent security researchers said they found bugs in recent months that allowed them to view the internal communications of OpenAI employees. They also found other vulnerabilities that would enable them to see the company’s internal computer code and view the chat logs of ChatGPT users. When the researchers contacted OpenAI about their findings, they said, the company initially disregarded them.
“OpenAI’s security seems to be about what you’d expect from a research lab that scaled at a blistering pace over four years and focused more on beating its competitors than securing its infrastructure,” said Joshua Saxe, the chief technology officer of the AI security firm Abundant Security.
«
This company increasingly looks like it’s playing with fire and yet doesn’t have a system for extinguishing fires.
unique link to this extract
| • Why do social networks drive us a little mad? • Why does angry content seem to dominate what we see? • How much of a role do algorithms play in affecting what we see and do online? • What can we do about it? • Did Facebook have any inkling of what was coming in Myanmar in 2016? Read Social Warming, my latest book, and find answers – and more. |
Errata, corrigenda and ai no corrida: none notified


