Start Up No.2759: OpenAI revenue disappoints, man versus robot, the Sad Wives of AI, BBC’s Brittin offers future plan, and more


The strides being made by LLMs in solving longstanding maths problems have led some mathematicians to worry about the future of their field. CC-licensed photo by J R on Flickr.

You can sign up to receive each day’s Start Up post by email. You’ll need to click a confirmation link, so no spam.


Due to a technical error (thanks for continually changing your layout, WordPress) the Thursday morning edition of The Overspill didn’t go out on email. It can be read here.) The missing links should also appear on the bottom of the email.


A selection of 9 links for you. Adds up. I’m @charlesarthur on Twitter. On Threads: charles_arthur. On Mastodon: https://newsie.social/@charlesarthur. On Bluesky: @charlesarthur.bsky.social. Observations and links welcome.


OpenAI annualised revenues $20bn less than previously signalled • Financial Times

George Hammond and Stephen Morris:

»

OpenAI’s annualised revenue is about $20bn less than the company had signalled, according to financial documents shared with investors, a massive gap likely to damp optimism about the growth of AI demand.

The company has recently told investors its revenues were approaching $50bn on an annualised basis at the end of September, far short of the $70bn reported by the FT and other media outlets late last month based on information that was provided to investors.

The metric, along with the equivalent figure for OpenAI’s rival Anthropic, is the most important indicator of overall demand for AI and underpins vast infrastructure spending and the growth of public equity markets.

US tech stocks fell sharply following the FT’s report on Thursday, extending losses from earlier in the session, with the Nasdaq 100 closing down 1.4%. Chipmaker Nvidia fell 2.9%, Oracle dropped 5.5% and Micron declined 4.8%.

The discrepancy arose from attempts by OpenAI’s investors to produce a direct comparison with Anthropic’s annualised revenues, said a person familiar with the matter. The pair calculate the figure in different ways, with Anthropic including the revenue from sales via cloud partners such as Amazon’s AWS and Google Cloud, while OpenAI does not.

Investors’ efforts to “gross up” OpenAI’s annualised revenue prompted reports that the figure was about $40bn in July, said the person.

The company later told its backers that its annualised revenues had jumped more than 70% since July, prompting reports that the figure was about $70bn at the end of September — a number the company did not deny.

However, the new investor presentation shows close to $30bn annualised revenues in July.

«

It’s a good amount of money but is it going to cover costs? And fund all those bonds? And data centres? No wonder the stock market hiccuped.
unique link to this extract


A man fought a ‘Terminator’-like robot in a cage. California called it illegal • The New York Times

Adeel Hassan:

»

The 6′ tall, steel-framed humanoid robot, which looked like James Cameron’s original “Terminator,” entered the cage, followed by a 5’5″ male human in a helmet and other protective gear.

You can probably guess what happened next. The robot, which was operated by a human pilot using a remote virtual-reality system, pummeled its fleshy opponent, Frankie LaPenna, repeatedly knocking him to the canvas and driving him into the walls of the octagonal enclosure.

Mr. LaPenna, a social media influencer, injured his hand while punching one of the metal robot frames during one of the three bouts he had with different robots. He landed a few punches, but each time he knocked a robot down, it bounced back almost instantly. The crowd of about 100 (humans, not humanoids) was thrilled.

The fight, promoted as “Human vs. Robot,” was staged on Sept. 18 in San Francisco by a tech start-up called REK, which stands for Robot Entertainment Kombat. It caught the attention of the California State Athletic Commission, which sent the company a cease-and-desist letter. The commission, which regulates professional and amateur boxing, kickboxing and mixed martial arts, had not sanctioned the event.

REK, which bills itself as “the humanoid robot fighting league” (“Real robots, real combat”) — celebrated the letter. “We made it boys,” its chief executive, Cix Liv, said in an online post. The letter said that the commission must grant approval to any boxing or mixed martial arts contest, match or exhibition that involves any human in the state of California.

Mr. Liv dismissed the regulator’s claims. “The law clearly states that a ‘match’ is between two persons,” he said in an interview, adding that state regulators were welcome to try to argue in court that a humanoid is somehow human.

…The event produced the most-viewed content that REK has so far shared online, but Mr. Liv said there wasn’t a plan to repeat it. Instead, the company plans to host the first fight between humanoids armed with blades on Friday night in San Francisco.

«

There’s dystopian, and then there’s whatever this company is up to.
unique link to this extract


Meet the Sad Wives of AI • WIRED

Alessandra Ram:

»

If I had to listen to another minute of my husband talking about Claude Code, I might have actually died. It was 11 pm in Berkeley, California, where I was home alone with our 10-month-old daughter, and 2 am in Cambridge, Massachusetts, where he was visiting for his newish job in AI. “JUST LOOK AT THIS!” he shouted. The FaceTime camera zoomed toward a laptop sitting on a hotel bed. “SEE?!”

See what, I thought. I wanted to shower. I still had to take the dog out.

“ARE YOU LOOKING?” he shouted again. I wasn’t. I was looking at our real baby. But that’s the thing. There are two babies in this household now: the small human one and the large language model. Both demand constant attention. Both keep us up at 2 am.

Is this a Sophie’s choice kind of situation? Please. I’d kill the AI baby in an instant.

There’s a strange and under-discussed side effect of the AI boom: what it’s doing to family dynamics. By which I mean: how it’s potentially destroying family dynamics. I’m sure this applies to all kinds of families, gay or straight, rich or poor, with any AI-pilled members. The technology is coming, has come, for us all. But for the purposes of this story, I mostly spoke to white-collar heteros in the Bay Area, because that’s where a certain psychological crisis seems most acute. Often it goes like this: He works in AI, and she does everything and anything else. Other times, it’s bleaker: He desperately wants to work in AI—or feels he must work in AI—and she wants him to do literally anything else.

Either way, the men go in and the women want out. How many? It depends on how you define “working in AI.” About 71% of “AI-skilled workers,” according to one report, are men, and there are roughly 35,000 open AI roles in the US at any given moment. Broaden that to include investors and you’re adding thousands more. Broaden it further to include every man who has mentioned to his wife that he is “looking at some opportunities in the space”—and we’re in the millions. Conservatively, that means hundreds of thousands of spouses, partners, and girlfriends, holding down the fort while someone mansplains the singularity to them. There are, in other words, a lot of us, and more of us are surfacing—gasping for air and a single conversation that doesn’t involve LLMs—by the day.

There’s a name for our ranks. I call us the Sad Wives of AI.

…Yana van der Meulen Rodgers, the chair of labor studies and employment relations at Rutgers University, has a blunt take: What’s happening in Bay Area households isn’t just a lifestyle story. It’s a labor market story. The AI boom, Rodgers says, is creating a “perfect storm” of forces reshaping household dynamics, playing out along predictably gendered lines.

«

It’s a great piece. (BTW those who find the other half absent while they mind the home and possibly child[ren] are “Single Married Parents”. Lots of them in this piece.)
unique link to this extract


BBC boss Matt Brittin details Silicon Valley revolution at broadcaster • Deadline

Jake Kanter:

»

Attempting to lift staff from the gloom of corrosive job-cut announcements, [new BBC director-general Matt] Brittin spoke about the BBC radically rethinking how it meets audience needs online by decentralizing decision-making power, embracing a sense that digital — not traditional broadcast — “can be flagship,” building and testing new online products quickly, and recognizing that it’s ok to “experiment and fail.”

In other words, Brittin outlined a Silicon Valley-isation of the BBC.

“We have to recommit to our mission, our public service mission, pursuing truth, bringing people together, boosting homegrown storytelling,” he told staff, per an audio recording obtained by Deadline. “We have to recommit to that mission. We have to reinvent how we do it. [We] have to understand and protect the magic of the BBC and change everything else, in order to serve those audiences.”

He continued: “I love the BBC. It’s full of words and discussion and slide decks and framing and reframing and reconstituting, and going around the houses, and actually, I’d like us to celebrate activity less, and outcomes more. And getting faster to outcomes that make a difference to an audience.

“Not [just], ‘We did this great marketing campaign,’ but actually, ‘It drove up watch time usage and active accounts,’ right? Or, ‘We did this piece of journalism, and it changed the law, and it landed with these audiences.’”

Brittin illustrated this by introducing BBC employees to Manon Dave, the head of future world design in the corporation’s Media Tech unit. Dave told colleagues that he spent time on holiday redesigning iPlayer without any internal limitations. He wants the streaming service to become a place where audience members say, “I want to iPlayer and chill,” though it is not clear if this means retaining the sexual connotations of the original “Netflix and chill” internet slang.

Dave’s vision for iPlayer included an AI agent called Iggy, which helps recommend and summarize iPlayer content, and can speak to audiences in different languages. Other ideas Dave presented to staff included a personalized “hero” picture at the top of iPlayer’s home screen, which picks out algorithm-led content recommendations based on past viewing habits. He also demonstrated “Vegas mode,” allowing viewers to “roll the dice” and see what iPlayer selects for them.

Brittin said Dave — who at one point during his presentation referred to the director-general as “my big homie” — had captured a “pioneering mindset” that he wants to see more of at the BBC. Brittin added that the BBC plans to begin testing some of Dave’s ideas with audiences “in the coming weeks.”

«

Certainly iPlayer needs to be better, and the BBC spends too much time gazing in awe at its navel. Yet it’s surprising what things do work. Apparently the message shown in the second half of World Cup football matches encouraging people to pay their licence fee led to people coughing up. Sometimes it’s the simple things that work.
unique link to this extract


UK motorists can now see live fuel prices on Google Maps • The Guardian

Jillian Ambrose:

»

Drivers will be able to see live petrol prices on Google Maps for the first time from Thursday, in a move that will help motorists shop around for the cheapest fuel.

Millions of motorists will be able to find the cheapest petrol and diesel prices by searching for a local forecourt in the Google app, in what could prove to be “a major development” in making fuel prices more fair, according to campaigners.

The tech company will use data from the government’s Fuel Finder platform, which displays real-time prices at 99% of forecourts, to show Google Map users the cheapest in their local area.

It is expected to make forecourt pricing more transparent and encourage competition between fuel retailers, as millions face record-high road fuel costs due to the global squeeze on supplies prompted by the US-Israel war on Iran. The average price of diesel in the UK recently hit a record £2 a litre, having risen by more than 40% since late February.

Edmund King, the president of motoring group the AA, said: “Getting transparent fuel prices on to Google Maps is a massive step forward and means most drivers will have easy access to pump prices. Hopefully, this high-level pump-price transparency will also encourage more competitive prices from retailers.”

«

The weird thing about this is that the Fuel Finder site works perfectly well. Stick in a postcode and you’ll get stations nearby, and you can pick which fuel you want. Nice use of open data, though.
unique link to this extract


OpenAI just carpet-bombed mathematics • The Atlantic

Konstantin Kakaes:

»

In the growing chorus of mathematicians revolting against AI companies, Hugo Duminil-Copin, who in 2022 received the Fields Medal, math’s highest honor, has perhaps put mathematicians’ concerns most vividly. In an essay published just before OpenAI announced last month that it had solved one of seven grand mathematical challenges known as the Millennium Prize Problems, he wrote that AI proofs “nuke the mathematical landscape, making it increasingly difficult to inhabit after each blast.”

If resolving a Millennium Prize Problem was like dropping an atomic bomb, then the results that OpenAI shared Tuesday were a mathematical carpet-bombing. Mathematicians had been bracing for the assault: OpenAI had teased that a new model had found solutions to “more than 100 long-standing open problems across most areas of mathematics.” When the drop came, it included 377 new proofs by an as-yet-unnamed proprietary model.

About a third are major proofs of conjectures that are famous across mathematics. Another third are significant within their mathematical subfield. The remaining third are either more minor results or variants. Hundreds of people had spent dozens of years trying to understand—and prove—the results that OpenAI released in a single day.

Mathematicians are still picking through the rubble. It is too early for anyone to have verified the OpenAI work in detail, but several mathematicians have told me that at least some of the papers appear not to prove what they claim to prove. (Every carpet-bombing has a few munitions that fail to explode.) OpenAI has already withdrawn three of its papers; still, “we expect mistakes to be quite rare,” an OpenAI spokesperson told me in an email. The company also said, as part of the initial announcement, that the model had attempted to solve about 3,600 further problems for which the company did not release successful proofs. OpenAI promised to pay mathematicians to study AI-produced results, although the company has yet to specify how generous the funding will be.

“We don’t believe the future of mathematics is set. We’re working with the math community to navigate the future collaboratively,” the spokesperson wrote. Nonetheless, many mathematicians are looking at that future with apprehension. They worry that having AI leap to solve proofs will sacrifice what the struggle to get there might have yielded. They worry especially about how they will train younger mathematicians to find that spark of life, or wanting to at all. And they worry that, if mathematicians have no reason to pursue the mysteries of their field, then the rest of us will stumble into a world run by machines whose workings nobody understands.

«

Did any of us expect that the first group of people to be put thoroughly out of work by AI would be mathematicians? Absolutely not. (Gift link.)
unique link to this extract


Google, Meta said to be paying premium for land internet routes amid Red Sea clash • Rest of World

Indranil Ghosh:

»

US cloud giants are facing steep prices to secure backup internet routes around the Red Sea as fighting rages over the Red Sea strait that carries most data cables between Europe and Asia.

More than 90% of data capacity between Europe and Asia runs through cables under the Red Sea. The cables enter the sea at Bab al-Mandab, a strait less than 32 kilometers (20 miles) wide between Yemen and the African nations of Djibouti and Eritrea.

The Houthis, a US-designated terrorist organization, seized Yemen’s side of the strait in September, including the island of Mayyun. On October 5, Saudi-backed government forces said they had retaken key positions around the strait and the port of Mocha — claims the Houthis denied.

In September, Google bought a pair of fiber strands running along Turkish state pipelines, paying two to three times the roughly €6m ($7m) that newer lines crossing Turkey are expected to cost, said a person familiar with the deal, requesting anonymity because the details are not public. Long-distance fiber is usually sold with a single upfront payment covering 15 years or more of use. Buyers also pay a separate annual fee for maintenance.

Microsoft said on September 23 that it plans to invest more than $400m in subsea and land links across the Middle East by 2030. Iraq also signed a contract with Qatari telecom company Ooredoo on September 10 to carry data toward Europe through an underground route from the southern port of Al-Faw.

Almost all major cloud companies are looking for backup routes around the Red Sea, the person told Rest of World. Google and Meta have started sending some live traffic through a land route across Iraq that they had previously held in reserve, the person said.

Google and Meta did not respond to Rest of World’s requests for comment by the time of publication.

«

unique link to this extract


Musk admits Tesla Robotaxi struggles to see pets at night. Lidar doesn’t • Electrek

Fred Lambert:

»

Elon Musk says the main thing holding back Tesla Robotaxi’s night hours is that the cars have a hard time seeing pets in the dark. His example was “grey kittens on grey tarmac.”

That’s a low-light, low-contrast detection problem, which is the textbook weakness of cameras and the exact thing lidar and radar handle. Musk has spent years calling those sensors a “crutch” and a “fool’s errand.”

Late Friday night, Tesla’s Robotaxi account announced that the Austin service is “now available until 11pm.” Until now, it shut down at 10 PM.

Musk reposted the announcement and explained what’s keeping the cars off the road later than that: “The main thing we’re trying to solve is making sure that we don’t run over pets when they’re hard to see at night. Literally trying to avoid grey kittens on grey tarmac in the dark.”

Some context on that extra hour. When Tesla launched Robotaxi in Austin in June 2025, the app took ride requests from 6 AM to midnight. Fifteen months later, the service closes an hour earlier than it did on day one. And it’s a small service. Tesla has barely scaled since launch, even with the addition of the Cybercabs last month.

A camera is a passive sensor. It works with whatever light bounces off an object, and it picks that object out by how much it stands apart from the background. A grey animal on grey pavement at night gives it very little of either.

Lidar is an active sensor. It fires its own laser pulses and times how long they take to come back, which gives the car a distance and a 3D shape for whatever is sitting on the road. It works the same at midnight as it does at noon, and it doesn’t need the kitten to be a different color than the asphalt. It needs the kitten to stick up from the road, and kittens, being 3D objects, tend to do that.

Radar does a similar job with radio waves and adds speed. It’s weaker on something that small, but it keeps working in the fog, dust and glare that blind cameras.

«

When Steve Jobs was wrong and recognised his mistake, he simply changed course. Musk’s weakness is he can’t.
unique link to this extract


“Uber agents,” undercover AI personas, and other ways newsrooms are using AI in investigations • Nieman Journalism Lab

Andrew Deck:

»

The release of the Epstein Files was a huge moment for AI in investigative journalism. Journalists across the U.S. woke up on January 30, 2026 to a Department of Justice drop of over 3.5 million pages of documents and tens of thousands of images and videos.

Duy Nguyen, who leads AI science research at the Times, noted that the PDFs in the Epstein Files would stack as high as the Empire State Building if they were printed out, and would take 11 years for one reporter to read. (Epstein sent an average of 65 emails every day for a decade.) It would take a reporter a month to listen to and watch all the audio and video clips.

Many newsrooms decided that the early organization and research into these documents was a task primed for AI technologies. Engineers from the Associated Press, NPR, and the Times led a session on how they built tools to help reporters sift through the documents.

NPR built an internal search tool that let reporters across the newsroom find the documents relevant to their beats, said Kriti Singh, a design technologist at NPR’s AI Labs. Her team classified documents by type (email, legal filing, flight log, witness list), grouped them by location (city, county, hotel, university), and extracted entities (making sure, for instance, that a search for “Prince Andrew” also surfaced files that mentioned “the Duke of York”).

The Times AI Initiatives team built the Epstein Files Engine, an internal chatbot to help reporters comb through the files. “There are so many sorts of threads that you can pull from such a big corpus, and the chat interface really allows [reporters] to dive deep,” said Nguyen. The engine’s interface was built with LibreChat, a free, open-source, self-hosted AI chat platform.

…Ultimately, more than 100 Times journalists posed more than 5,000 questions to the engine, and it contributed to at least 20 published stories. “This was a signifier of just how powerful an agentic chat interface could be in a newsroom,” said Nguyen. (His team recently published an academic article detailing the tool’s development.)

«

(Thanks Gregory B for the link.)
unique link to this extract


• Why do social networks drive us a little mad?
• Why does angry content seem to dominate what we see?
• How much of a role do algorithms play in affecting what we see and do online?
• What can we do about it?
• Did Facebook have any inkling of what was coming in Myanmar in 2016?

Read Social Warming, my latest book, and find answers – and more.


Errata, corrigenda and ai no corrida: none notified
Start Up No.2758: LLM reverse engineers Adobe clones, ChatGPT does your school photos, the Disney adult debtors, and more


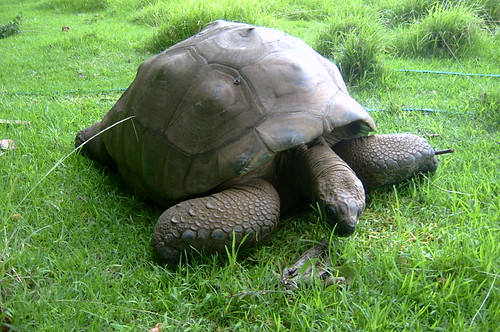
The tortoise known as Jonathan is thought to be the oldest living land animal. Does his genome explain how he’s so long-lived? CC-licensed photo by St Helena on Flickr.

You can sign up to receive each day’s Start Up post by email. You’ll need to click a confirmation link, so no spam.


A selection of 9 links for you. Lettuce find out. I’m @charlesarthur on Twitter. On Threads: charles_arthur. On Mastodon: https://newsie.social/@charlesarthur. On Bluesky: @charlesarthur.bsky.social. Observations and links welcome.


“Software is over”: bold AI developer takes aim at Adobe with open source clones • Ars Technica

Kyle Orland:

»

For a while, those hoping to avoid the difficulty and expense of dealing with Adobe’s Creative Suite have been able to use several free and/or open-source alternatives that replicate some or all of those capabilities. Now, one developer is using AI-powered reverse engineering to mimic the look, feel, and functionality of Adobe’s well-known software with what he hopes will soon be perfect fidelity.

Artcraft got its start last year as a “controllable AI for artists” that allows for precise post-generation editing of AI-crafted images and videos. Over the weekend, though, the brand debuted its pivot to a suite of seven open source apps recreating the user interface and tools found in Adobe’s Photoshop, Illustrator, Premiere, Lightroom, After Effects, InDesign, and Acrobat Pro.

In announcing those new apps on Reddit earlier this week, software developer Brandon Thomas said he used Anthropic’s Claude Opus 5.5 to create “clean-room replacements” for Adobe’s closed source software in Rust (with WebAssembly versions available for use in a browser). And while commenters on Hacker News and elsewhere have taken pains to point out the new software’s many current shortcomings, Thomas make the grandiose promise that the current “super early alpha” state will soon lead to something just as functional as anything Adobe has ever put out.

“We’re going to reach 100% [feature] parity within a month,” Thomas stated on Reddit of his plans to quickly squash bugs and add features with the help of community reports. Days later, on Hacker News, he amended that position slightly to say that “99% parity will take a while, but I’m sure it’ll be measured in months and not years.”

Thomas, who says he has about a decade of experience working on large-scale Rust projects, wrote on Hacker News that he was inspired to create his own open source Adobe software alternatives after being “bit by the dark pattern ‘cancellation fee’ one too many times.”

«

So Adobe sort of brought this on itself? But it was inevitable, in a monkeys/typewriters sort of way: give enough people access to LLMs that can reverse engineer software, and one of them will be annoyed enough at Adobe to try to generate open source as-good-as products. As he says, it might take a while, but the question is whether the extra 5% or 10% he can’t do is what a significant proportion of people need.
unique link to this extract


‘ChatGPT ftw’: parents are using AI to skip kids’ school photo day • Fast Company

Jude Cramer:

»

With a new school year underway, kids everywhere are saying “cheese” for school picture day—but some penny-pinching parents are cutting photographers out of the equation.

In their place, those parents are employing artificial intelligence to generate picture day-style images of their children. Others are getting their kids’ pictures taken as normal, but avoiding paying for the final images by using AI agents to erase watermarks from the proofs. Both methods may be cheaper than shelling out for professional pictures, but they come with their own hidden costs.

On TikTok, user Carlie Bond went viral for what she tagged as a #MomHack: taking photos of her three school-age children against a plain backdrop, then putting them into ChatGPT with the prompt, “Keep them exactly the same but make it look like a school picture.”

ChatGPT added a standard gradient backdrop to each image, making them look much like the standard school pictures from leading companies like Lifetouch and Cady Studios.

“School pictures x3 kids?? In this economy?” Bond wrote in her caption. “So we took our own and let my good friend Chat help us out 🤭 And honestly … I’m not mad about how they turned out.”

…But Bond’s commenters weren’t all on board with her cost-cutting strategy. Several pointed out that AI platforms like ChatGPT tend to distort images during editing. “Every time I put a photo into ChatGPT, it changes how the person looks no matter what I tell it,” one user complained.

Others worried about the implications of feeding photos of children into ChatGPT. “You are putting your children’s image and likeness through AI that can be utilized by AI later and stored in its memory,” one commenter cautioned.

«

On the latter point, pretty sure if there’s any image of those children anywhere on the internet then it will have been slurped up. On the former point – about distortion – well, are school pictures ever a true representation?
unique link to this extract


The Social Reckoning film review: Facebook sequel is Jaws if the shark ate everyone and kept swimming • Financial Times

Danny Leigh:

»

Last time we saw Mark Zuckerberg, he was grimly waiting on a Facebook friend request. We in this context are movie audiences, that last encounter coming with The Social Network — director David Fincher and writer Aaron Sorkin’s barbed account of a boy prince of tech, played by Jesse Eisenberg. 

The year was 2010. Prehistory. For Zuckerberg, so much still lay ahead, from allegations that Facebook enabled the genocide against Rohingya Muslims in Myanmar to the embarrassment of failed 3D virtual world the Metaverse, while extensive research has suggested deep harms from Meta products. And now, after it all, his personal wealth is reported to be more than 60 times greater than it was back then.

It leaves a lot to catch up with in The Social Reckoning, a hacky, frustrating sequel written and directed by Sorkin. Events are pared back to a crunch point. In 2019, we meet Frances Haugen, strait-laced Facebook data scientist. In 2021, she testifies to Congress about the company profiting from misinformation. The movie mostly takes place between. Haugen is played by Mikey Madison, an Oscar winner for Anora. Jeremy Allen White co-stars as Jeff Horwitz of the Wall Street Journal, to whom she first brings word of algorithmic wrongdoing.

…If social media has made us more stupid, the movie treats us accordingly. A generation ago, Sorkin found fame writing TV political drama The West Wing. His secret then was making viewers feel smart. Now he seems to be addressing the concussed. When Madison reveals that, in 2016, 64% of new members of extremist groups on Facebook were led there by the company, the fact is instantly repeated twice. When one crisis follows another for Zuckerberg, characters wail: “The timing couldn’t be worse!”

«

unique link to this extract


How long until AI hacks everything? • The Atlantic

Matteo Wong:

»

“It’s a matter of months, or maybe a year, in which the task of securing the software foundation of civilization will have to be solved,” Stanislav Fort, a former Anthropic researcher who is now the chief scientist at the cybersecurity firm AISLE, told me. And AI is not only making cyberattacks more effective but also increasing the surface area worth hacking. Breaking into a website or executing a ransomware attack takes time, Fort said, so hackers have traditionally chosen large targets with sizable payoffs. But cheap, tireless hacking agents mean any organization or person might be worth targeting. At the same time, the cybersecurity professionals I spoke with were confident they could rise to the occasion. “If we step up our game in cybersecurity, as a field, we can definitely meet the challenge stemming from AI,” Fort said.

The cyberattacks on Minnesota water facilities this past summer offer a preview of things to come. Iran-linked hackers disrupted dozens of water utilities in Minnesota, many in small communities that might not have a dedicated cybersecurity person on staff. “We were fortunate that there was a very alert operator that said, ‘Hey, I saw a pump go offline,’” John Israel, Minnesota’s chief information-security officer, told me. The state received a report from the operator around 3 a.m., and within two hours began investigating and responding. The hackers targeted a weakness in industrial computers that had been announced by the Cybersecurity and Infrastructure Security Agency only days earlier.

…Although AI was not directly implicated in the Minnesota cyberattacks, Emily Zimmer, a spokesperson for Minnesota IT Services, told me, “we assume most adversaries use AI” to amplify their attacks. In other words, it’s hard to imagine a hacker not using the technology today.

«

Open source LLMs will only make this more and more common; all that prevents them becoming widespread is the amount of computer power (especially RAM) needed.
unique link to this extract


Are Disney adults the happiest debtors on earth? • The New Yorker

Amelia Tait:

»

In 2023, Ashley, a freshman at Quinnipiac University, in Connecticut, had fifteen thousand dollars in her bank account. Excited by her newfound freedom as a college student, she decided to start going on solo trips. Walt Disney World, in Orlando, Florida—a place she had fallen in love with as a child, after visiting for the first time when she was four—seemed like an obvious choice. She went during her winter break. Then she returned, six times, in two years. “It’s just so magical,” she explained. “It keeps drawing me back.” Soon enough, her account balance had dwindled to just five dollars.

Last year, Ashley landed a job with the Disney College Program, a semester-long internship during which college students and recent graduates serve in entry-level roles throughout the parks. For around four hundred dollars a week (her salary, after Disney deducted rent for her company-sponsored housing), she worked as a PhotoPass photographer, taking pictures of guests as they enjoyed various attractions. One of the perks of being in the program was that she had free access to Disney World when she wasn’t on the clock, and so she’d often hang around in the park, spending liberally on food and merchandise. (She collects Disney pins.) As a result, she said, “a lot of my money went straight back to Disney.” She also spent more than what she was earning, accumulating roughly a thousand dollars in credit-card debt, which she had to ask her parents to help pay off.

So-called Disney adults have become a subject of online fascination, with many people now questioning how much it costs to be one. Almost two million people have watched a video, posted in November of 2025, in which a YouTuber asks Disney visitors how much debt they have. It’s a genre of content that has become more popular, recently, with critics seizing on it as evidence that the Disney-obsessed are not only culturally but financially bankrupt.

«

Obsessions take many forms. Turns out visiting Disney is one of them.
unique link to this extract


‘Jonathan’ is the oldest land animal on Earth. He could hold the secrets to defying death • 404 Media

Becky Ferreira:

»

Jonathan the tortoise, the world’s oldest living land animal, is still chugging along at the ripe age of roughly 194. Now, scientists have discovered some of the secrets to Jonathan’s longevity by sequencing his genome for the first time, according to a study published Wednesday in Science Advances.

Jonathan, a Aldabra giant tortoise (Aldabrachelys gigantea), hatched around 1832 in the Seychelles archipelago, and he was already in his twenties when Charles Darwin published On the Origin of Species. In his fifties, Jonathan was brought to the remote island of Saint Helena, along with three other tortoises, as a gift to the British colonial governor in the 1880s. He has lived there ever since. 

Aldabra giant tortoises often become centenarians, but Jonathan is a major outlier even for his species as he approaches nearly 200 years on this planet. To better understand his extreme lifespan, researchers evaluated Jonathan’s genome based on swabs of his cheeks and compared it with the genomes of several other tortoises, including a 36-year-old named Tank.  

The results revealed that Jonathan has “unique gene variants in most aging pathways” including DNA repair, insulin regulation, mitochondrial function, and “low entropy” methylation, reports the study. 

“Aging is very complicated, and there’s all these different hallmarks,” said Stephen Clark, an aging researcher at the non-profit Kallel Foundation and an author of the study, in a call with 404 Media. “That’s why this Jonathan study is so interesting. We’re still just at the very beginning of trying to understand aging.”

«

In the meantime, just move veeeeeeeery slowly until they have it all worked out.
unique link to this extract


Weight-loss drugs show signs of slowing biological aging, say drugmakers • MIT Technology Review

Antonio Regalado:

»

Popular weight-loss drugs may do more than help people shed pounds. They might also melt away the years.

Drug giants Eli Lilly and Novo Nordisk say patients taking their drugs age less quickly, according to readouts from molecular “aging clocks.” Such clocks assess a person’s biological age by looking at changes to DNA that accumulate with time, or, in newer versions, by tracking levels of key proteins.

Both companies found that overweight or diabetic patients taking the drugs, called GLP-1s, had reduced biological age compared to those taking a placebo, although the difference varied widely, depending on which type of clock was used, and what organ was tested. 

Overall, the difference was around “two to three years,” according to Nikolaj Roed, a global project leader at Novo, who says the company has been seeing “improved biological age in our patients across trials and across different tissues.” 

The findings add to wide speculation among scientists that GLP-1 drugs, as they are known, are acting on basic causes of aging and might be a true longevity treatment.

“Two years is a pretty strong effect, in my book,” says Steve Horvath, a professor at the University of California, Los Angeles, who’s credited with inventing aging clocks. Horvath says the emerging data could provide “evidence that these GLP-1 drugs are actually what is known as geroprotectors, medications that slow or possibly even reverse biologic aging.”

The companies shared their findings over the weekend during Aging Research & Drug Discovery, a conference devoted to seeking scientific remedies for old age. While that quest has not yet produced any clear-cut success, some scientists now think Novo’s drug semaglutide (sold under the names Ozempic and Wegovy) is coming close.

“In an unhealthy population, I do think it’s an anti-aging drug,” says Vadim Gladyshev, a Harvard biologist who assisted Novo with its molecular measurements. “But in a healthy population, no one knows.”

The drugs cause weight loss by stimulating a receptor, GLP-1, that tells your brain you’re not hungry. Yet real-world studies have shown much wider benefit. The drugs improve kidney function, reduce blood pressure, and even sharply cut the overall chance of death.

«

Maybe we’ve just been underproducing GLP-1 for all these millennia?
unique link to this extract


How Britain learned to love Chinese cars—especially a look-alike Range Rover • WSJ

Stephen Wilmot:

»

When Mark Thewlis went looking for a new family car this summer, he was struck by how much cheaper the Jaecoo 7 was than luxury brands with a similar look and feel. 

The 33-year-old from England’s south coast calculated the upfront cost of his preferred version of the Chinese sport-utility vehicle at the equivalent of around $50,000, half the price of a visually similar Range Rover model. Its resemblance to the 56-year-old British luxury brand has earned the Jaecoo a double-edged nickname: the Temu Range Rover.

“My first reaction was: What’s the catch?” he said. A test drive convinced him that buying the Jaecoo was a “no-brainer.”

No big industrialized economy has embraced Chinese cars more enthusiastically than the UK, where Brits like Thewlis are being won over by the combination of affordable prices with status-signaling styling and technology.

The Jaecoo 7, made by China’s Chery Automobile 9973 -5.39%decrease; down pointing triangle, was Britain’s bestselling vehicle in September, an important sales month in the UK. In the first half of 2026, almost every sixth car sold in Britain bore a Chinese brand, according to Schmidt Automotive Research, a higher proportion than in any other European country except Norway.

Britain’s vehicle imports from China have almost doubled this year compared with the same period in 2025. Only Russia and Brazil—developing economies that mostly buy cheaper models—have imported more. Cratering sales in China, the world’s largest car market, have encouraged its manufacturers to look for growth overseas.

The UK, a cradle of the car industry, showcases what could happen in America if Chinese cars were let in. “Range Over!” began a press release trumpeting the Jaecoo’s early sales success, winking at its likeness to the Range Rover Evoque.

«

The Range Rover brand might be strong, but the actual quality of the cars has been terrible for years; an open (garage) door for the Chinese companies to drive through. The appearance of the new Range Rovers is also strange, as though they had melted a bit. (Thanks Joe S for the link.)
unique link to this extract


Changes coming to this site • Erdős Problems Blog

Thomas Bloom:

»

I launched the site on 28th May 2023, with just over 200 problems; it has grown steadily since then. The biggest change came in August 2025 when I added a comment feature. The site now hosts 1221 problems, over 9000 comments, and almost 2000 registered users. The site typically receives between 10,000 and 25,000 unique visitors each day.

The first few months after introducing the comment feature saw a huge increase in activity, just as I had hoped. A vibrant community arose; people shared ideas on how to solve problems, made observations, gave corrections, and suggested missing references and solutions. Many papers were written and new collaborations formed.

Unfortunately, this level of activity has not been sustained. Some decline was inevitable: over time, many of the natural observations will have been made, mistakes corrected, and discussions between collaborators would move offline. This natural evolution has been dramatically sped up by the coincidental rise of AI and its ability to solve some problems with minimal human intervention.

The main way that people publicly interact with the site now is to advertise their AI-generated proofs, often without any attempt to explain them, but as a way to record a (increasingly meaningless) priority claim.

This is very different to what I imagined, and I don’t want to manage a website which does this.

I believe that websites with this function should exist — places where people can record AI-generated proofs, even if purely formal with no human understanding, to save others wasting their tokens generating the same proof, and so that other people can access and use them if they desire. There are now several candidates for such repositories, and if managed responsibly, they can serve a useful role in the mathematical ecosystem. I personally don’t want to manage one.

Just as one does not open a restaurant in an abattoir, it is important that there be a separation between such repositories and a site which aims to promote the actual questions, place them in an appropriate context, and give a useful overview of the current state of human understanding.

«

(Erdös problems are mathematical puzzles set by the famous mathematician.)
unique link to this extract


• Why do social networks drive us a little mad?
• Why does angry content seem to dominate what we see?
• How much of a role do algorithms play in affecting what we see and do online?
• What can we do about it?
• Did Facebook have any inkling of what was coming in Myanmar in 2016?

Read Social Warming, my latest book, and find answers – and more.


Errata, corrigenda and ai no corrida: none notified

Start Up No.2757: Asos app shows hacking message, the gamer decompilation, Google data centre halted in Finland, and more


In the age of physical tape, we knew what “recording” was. But might modern digital devices listen without recording? CC-licensed photo by Carbon Arc on Flickr.

You can sign up to receive each day’s Start Up post by email. You’ll need to click a confirmation link, so no spam.


A selection of 9 links for you. Reely hard. I’m @charlesarthur on Twitter. On Threads: charles_arthur. On Mastodon: https://newsie.social/@charlesarthur. On Bluesky: @charlesarthur.bsky.social. Observations and links welcome.


“ASOS hacked”: app users receive notifications sent by hackers • BBC News

Joe Tidy and Liv McMahon:

»

Asos says it is investigating “unauthorised activity” involving third-party platforms it uses after customers received a notification from its app sent by hackers.

Dozens of people told the BBC they received the strange “ASOS HACKED” message from the clothing and beauty store’s app on Tuesday morning – with some saying it left them “scared” to open the app.

The notification was addressed to the company’s data protection officer and IT teams in what cyber security experts said looked like a “brazen” extortion attempt.

Asos acknowledged the “unauthorised customer notification” on Tuesday afternoon, saying some “basic personal information” may have been accessed. In an email to customers on Tuesday night, the company apologised and urged customers not to engage with the notification. And it said the website and app are “operating as usual” promising customers they can “shop with confidence” while it investigates the incident.

The company has not as of yet informed the UK’s data watchdog, the Information Commission’s Office (ICO), about any breach. Exactly how many Asos customers received the notification on Tuesday remains unclear, but Google’s Play store says the ASOS app has been downloaded to android devices more than 10 million times.

The British retailer has a substantial global footprint – serving around 17 million customers each year across more than 150 markets.

Some Asos app users in Australia, France, Sweden and the Republic of Ireland had also received the notification, according to local reports on Tuesday.

Hackers seeking to pile pressure on potential victims by informing their customers is rare, as most extortions happen in private, so this incident may go down as a significant moment in cyber-attack history.

Shares in the company fell by around a tenth on Tuesday.

«

Asos is in hot water for not acknowledging the hack, but the biggest concern is what it implies about how badly the company has been hacked.
unique link to this extract


Viral Fallout and MW2 AI decompilation projects hit with DMCA • The Gamer

Nazmul Roosevelt:

»

DMCA takedowns for mods and fan overhauls have been happening for years, so it makes sense that decompilation projects, especially the ones assembled quickly and shared widely on social media, are now drawing the same kind of attention. These projects have exploded in number over the past week or so, but many rely heavily on generative AI. Even well‑known efforts like Ship of Harkinian use some form of genAI, despite beginning long before the current wave of vibe‑coded recreations.

The projects that went viral this week were built with far more aggressive AI assistance. One of the first was Fallout: New York. ChrisFirst shared a clip on Twitter showing a browser‑playable recreation of Fallout built with Claude Opus 5.5. It had quests, dialogue trees, VATS, a working Pip‑Boy, and an entire city generated without any texture or sound files. Every building, weapon, face, and ambient noise was “generated by code.” The post pulled in millions of views before ChrisFirst shared that he received a cease-and-desist from Bethesda and shut the project down.

The second project that’s since been taken down came from Maurice Heumann, who used generative AI to decompile Modern Warfare 2 on PC. He said he had seventeen agents working at the same time, reconstructing the game faster than any manual effort could. According to him, the game was already playable, most bugs were fixed, and he had even earned a nuke. Activision responded by removing the footage from his post and blocking access to the site hosting the code. Heumann later shared that his AI agents kept deleting his files.

The difference seems to come with scale. Ocarina of Time running in ultrawide at 280 frames is a transformative example of what was previously capable on native hardware. It’s impressive to see, even if the game was never meant to be viewed that way. The strongest decomp projects show evidence of careful manual work, but the rapid spread of AI‑assisted recreations is pushing the space into territory that publishers can no longer ignore.

«

What’s happening is that gamers can now use AI agents to decompile the executables of games, and then get those recompiled for other platforms, or add new elements that weren’t there before. And publishers don’t like it when such work is made public. (Obviously they can’t see any private work.)

Feels like this might drive games companies to cloud-based services which can’t be decompiled because they’re never running on the user’s computer.
unique link to this extract


Silicon Valley thinks AI will kill jobs. Economists are not convinced • Financial Times

Delphine Strauss:

»

The most worrying development is a cross-country slowdown in entry-level hiring in tech-related occupations — consistent with AI turbocharging the productivity of senior staff while taking over routine tasks done by juniors.

But there is no consensus on the cause. “Unemployment of young graduates has worsened since 2015. It’s a long-term trend. AI is clearly not the only factor,” Broecke argued, citing a potential oversupply of graduates, the rise of remote work and high interest rates.

The absence of aggregate job losses may simply be the calm before the storm. “Talk to executives in the non-tech sector — those who use AI as customers — and many say they don’t need as many workers as they did before AI,” Johnson said. “It is not yet in the numbers . . . but the automation threat is very real.”

Modelling by the Anthropic Institute, published last month, included an extreme scenario where rapid gains in AI’s capabilities cut “cognitive” employment by a fifth by 2030, leaving one in five white-collar workers and one in 10 of all workers unemployed.

The model is highly sensitive to underlying assumptions. The extreme scenario assumes AI will rapidly become able to perform most tasks without human oversight, will be widely adopted and will generate big productivity gains.

Other scenarios show more modest change, but Anton Korinek, who led the modelling, said he “personally put more weight” on those showing a rapid increase in AI adoption from 2028, with the technology becoming able to rival and replace senior executives, not just entry-level staff.

In practice, companies may be slow to shed workers even when AI tools can do the job. Broecke of the OECD said: “There is the cost of technology. There are legal barriers, social preferences, ethical issues. There are all sorts of reasons why something that is theoretically possible will not happen in practice.”

«

unique link to this extract


Google told to halt work on datacentres in Finland over environmental concerns • The Guardian

Miranda Bryant:

»

Google has been ordered to temporarily stop work on two datacentres in Finland after failing to do the necessary environmental impact assessments on its construction sites.

The planned datacentres in Muhos and Kajanni are part of a €13bn (£11bn) project across multiple sites in northern Finland by the technology company amid huge demand for space to house online infrastructure.

It comes after it emerged that Tuike Finland Oy, the company representing Google, had felled 330 hectares (815 acres) of forest in Muhos without completing an environmental impact assessment (EIA).

In Kajaani, the company has reportedly been logging across just under 200 hectares (494 acres) of land.

The Finnish Association for Nature Conservation said the sites had been reduced to “sand”, blaming the oversights on the “overheated” market for new datacentres.

On Tuesday, the Finnish Licensing and Supervision Authority (LVV) said it had issued a notice to the company to “immediately suspend” – by 23 October at the latest – “preparatory measures that significantly change the environment” of the two sites until the environmental impact assessment had been completed. Google has until next Wednesday to submit a written explanation.

The EIA is ongoing and expected to be completed later this year. But Google has gone ahead with “extensive preparatory measures”, including removing trees, stripping topsoil and constructing site roads, LVV said.

Tommi Muilu, the head of the environmental department at LVV, said: “In our opinion, the measures in question will change the environment and cause impacts, the identification and assessment of which are among the key objectives of the EIA procedure.”

«

The photograph in the story suggests that Google got a long way along in its felling before, oh, did we not do the impact assessment? Well, there’s the impact: mud where there used to be forest. But don’t worry! AI will solve the climate crisis just as soon as it’s finished making it worse.
unique link to this extract


We can’t just change the definition of “recording” • The Verge

Victoria Song:

»

The Apple Watch has had a microphone for ages, mostly for Siri and taking phone calls from the wrist. Of the four Audio Intelligence features, two have caused the most debate online: Live Rewind and Siri Recap. The former produces a transcript of the past 15 seconds, whereas the latter can generate high-level summaries of the conversations you have throughout the day.

In other words, Ray-Ban Meta glasses take photos and record video, which is stored on your phone. This rumoured Apple approach would mean cameras can see you, microphones can hear you — but neither is “saving” anything.

Does this count as recording? Apple doesn’t comment on rumours, but based on how it’s publicly communicated its Audio Intelligence privacy philosophy, I’d argue the company doesn’t think so. Apple says these features don’t save any audio. The raw data is deleted once it’s finished processing in a separate, secure exclave on the S11 [Watch] processor. Any information sent to the cloud is through [Apple’s] Private Cloud Compute and is therefore inaccessible to Apple or third parties.

It’s not just Apple, either. Sandeep Waraich, Google’s senior director of wearables, told The Verge in a conversation that Google is also mulling this concept. What if, he posited, cameras on smart glasses didn’t record data? For example, if the glasses could process visual data in your environment using AI, but didn’t save any footage for posterity. In that way, Waraich argued, the camera could “just” be an image sensor.

By these definitions, something has to be preserved and reviewable to be “recording” you. But wouldn’t any text transcripts generated by a smart home camera or smartwatch count as preserved and reviewable? Or, in trying to make AI hardware more palatable, are tech companies relying on what can be subpoenaed in court?

«

Sounds like it’s the latter. I guess we’ll find out when the American or Chinese governments demand to access it. You can’t subpoena data that’s not there any more.
unique link to this extract


ChatGPT is adding real cartoonists’ signatures to fake New Yorker cartoons • Nieman Journalism Lab

Andrew Deck:

»

At the pearly gates, Dolly Parton, in a sparkling gown, stands arm in arm with Tim Curry, dressed as Dr. Frank-N-Furter. “I knew I chose the right plus one,” Parton says to God, who is standing at heaven’s reception desk.

That’s the premise of a cartoon that went viral on Twitter in the days after the legendary entertainers’ deaths in late August. One tweet of the cartoon received 25,000 likes, while other versions of the image circulated on Facebook, Instagram, and Bluesky.

In the bottom right corner of the cartoon is the pen name “BLOPER,” the signature of New Yorker cartoonist Brendan Loper. But Loper didn’t draw the cartoon, or sign it. It was generated by ChatGPT and first posted to Facebook by a Dolly Parton fan. In the comments section of her post, she wrote she had simply asked ChatGPT to make “a New Yorker-style cartoon.”

“I had people writing to me about this cartoon, asking if it was mine,” Loper told me. First came a text from his twin brother, whose friend had seen the AI-generated image. Emails and DMs on social media from strangers followed. “It was very surreal,” he said.

…Loper already knew his work was “out there, getting harvested for all of this [AI] training,” he said. But an image generator faking his signature felt more personal. “I’m not a territorial person, but my name is my name. It felt very much like a violation of my personhood.”

…After I notified OpenAI of the issue, ChatGPT began to output a new message when I asked it to generate New Yorker-style cartoons: “This prompt may violate our guardrails concerning similarity to third-party content.”

«

“Guardrails”. Okey doke. (Thanks Joe S for the link.)

unique link to this extract


Steve Jobs said this kind of device would be “terrible”. Sixteen years later, Apple seems set to release it • Inc.com

Kit Eaton:

»

It’s impossible to think of Apple without a memory of Steve Jobs surfacing—whether it was his stylish product reveals, his blunt emails, or his vision for the future of Apple. But visionary as he was, Jobs wasn’t always right, and next week we may see more concrete proof of this with the release of a new device that Jobs once claimed would be “ergonomically terrible.” A slew of rumors suggest Apple is poised to release a redesigned MacBook Pro—and the new, super-slim laptop will (gasp!) have a touchscreen. 

Of course, iPhones, iPads, iPod Touches, and other Apple devices have had touchscreens for years, but these devices were designed from the start to be touch-friendly, with everything from the shape of the device to the design of the user interface being built around the touch experience. Back in 2010, three years after the iPhone’s launch, Jobs was speaking at an Apple event about the idea of bringing touchscreen tech to MacBooks. Apple had completed “tons of user testing,” presumably using prototype touchscreen Mac devices, and had concluded that “it doesn’t work. It’s ergonomically terrible.”

…But according to several different rumors, Apple will actually reveal a Mac with a touchscreen as part of its October event, set to happen on October 13 per prolific Apple leaker Mark Gurman of Bloomberg.

We may see the touchscreen HomePad smart-home controller arrive at the same time, representing a whole new category of device for Apple, along with refreshed AirPods and possibly a home security camera system. (Remember: All of this is unconfirmed.)

«

It’s true: you can read this Wired article from 2010, where Jobs is dismissive of the idea:

»

“We’ve done tons of user testing on this,” Steve Jobs said in Wednesday’s press conference, “and it turns out it doesn’t work. Touch surfaces don’t want to be vertical. It gives great demo, but after a short period of time you start to fatigue, and after an extended period of time, your arm wants to fall off.”

«

Indeed, at the time everyone agreed that touchscreens were a terrible idea for a laptop. Especially if it was super light – which the new laptops are rumoured to be.
unique link to this extract


Apple and a Hacker’s Future • Stratechery

Ben Thompson:

»

My computer got hacked, which is always embarrassing to admit, because it was my fault; the vulnerability that was exploited is detailed in this Ars Technica story:

»

Dutch officials have warned that a high-severity macOS vulnerability that allows attackers to execute malicious code is under active exploitation. “The NCSC has received a notification indicating that active abuse of this vulnerability has been observed on multiple systems on which port 5900 was accessible from the Internet,” the Netherlands National Cyber Security Centrum warned earlier this week. “In all these cases, root had been accessed on the affected system and a Monero crypto miner had been placed.”

The vulnerability, tracked as CVE-2026-65400, received a patch from Apple last week for macOS Tahoe, Sequoia, and Sonoma. The vulnerability, with a severity rating of 7.1 out of 10, stems from a bug in the macOS screen sharing capability, which allows a remote party to view the screen and control the keyboard and mouse while a machine is turned on. A flaw in the “state management,” which keeps track of preceding events, user interactions, variables, and other system states, is the underlying cause.

«

…Claude in its Code harness seems to handle wide-ranging discussions better than Codex, and it follows my instructions about writing things down in the way I want to more gracefully. Code also has a persistent monitoring tool that I utilize as an inbox to capture interactions with a status board I built to visually track everything I have written down, as well as interactions with a Telegram bot (OpenAI’s new Dots achieve some of this functionality, which has been sorely needed in ChatGPT/Codex).

Said monitoring tool stands down every 30 minutes, so my agent restarts it on a schedule; that is what triggered an URGENT notification from Claude.

«

What’s remarkable is that Claude spotted the hack – which files had been changed, what had been added, precisely when it happened, and how to remove it. But Thompson has a strong point: Apple’s “install security updates automatically” option doesn’t automatically install security updates if they’re included as part of OS updates that you have chosen not to install automatically.

As he points out in the Dithering podcast with John Gruber, Apple needs to bend to the problem of allowing agents to run without needing stuff like Screen Sharing and constant clicking of security alerts. The simple solution: reanimate Mac OS X Server, designed for exactly this challenge. Which Apple discontinued in April 2022, just months before ChatGPT turned the world upside down in November that year.
unique link to this extract


A slow ceding of agency • Hot Takes

Adam Singer:

»

A voice or chat interface is in my opinion inferior to visually seeing all options (not just options the AI decides to show) presented in one window, with another window for your own research or context. As an adult I have a workstation with two monitors, plenty of screen real estate. I do not require an infantilized view, and since I am not cognitively impaired also do not require a machine to make decisions for me. Notably, I also don’t use mobile to accomplish these tasks, which are tasks suited for an office. Other people have no boundaries nor opinions on computing best practices and simply use mobile for everything. They’re measurably less happy by the way. I can see why they’d want to use AI instead, as they already don’t really like computing, do so without thought for ergonomics, sophisticated decision-making etc. Perhaps some percentage of the population doesn’t really want to do anything.

I’ve watched for years as the tech industry manically promotes the next thing merely because it’s new. But as agents are pushed on us, AI is especially pernicious because it presents a pretty large ceding of agency to machines. And while I want machines to do some things for me, I don’t want them to do everything. I personally disliked the time I even had a human personal assistant to book travel at a previous job. I prefer to do things myself (I also don’t pay someone else to work on my yard, aka get exercise outside for me, that’s enjoyable, too).

I want to live my own life, and that involves being capable and practiced at things, and more importantly, the one who decides the details. You start to lose something when you outsource too much of this. There’s a reason we encourage older people to stay socially, physically, and mentally active, and why cognitive stimulation is incorporated into care for people as they age. Using your brain, making decisions, remembering things, and learning skills are all forms of mental engagement. What happens when we systematically remove those little opportunities for agency and effort from everyday life, across an entire society? I don’t think we’ve really thought through what that means.

The irony here is so much of Silicon Valley talks about the importance of agency, and yet they themselves are building products that remove it from the user. A bit of “agency for me, not for thee”, and here, they are happy to become the intermediary in your life.

«

As you can see, Singer is not a fan of Silicon Valley’s obsession with AI agents.
unique link to this extract


• Why do social networks drive us a little mad?
• Why does angry content seem to dominate what we see?
• How much of a role do algorithms play in affecting what we see and do online?
• What can we do about it?
• Did Facebook have any inkling of what was coming in Myanmar in 2016?

Read Social Warming, my latest book, and find answers – and more.


Errata, corrigenda and ai no corrida: none notified
Start Up No.2756: BT to absorb failing TalkTalk, Siberia watches for plague, Norway eyes smart glasses law, RAM hike to go on, and more


You might think that being an electrician or builder is AI-proof, but could you actually survive doing it? CC-licensed photo by Rainier Martin Ampongan on Flickr.

You can sign up to receive each day’s Start Up post by email. You’ll need to click a confirmation link, so no spam.


A selection of 10 links for you. Sparky. I’m @charlesarthur on Twitter. On Threads: charles_arthur. On Mastodon: https://newsie.social/@charlesarthur. On Bluesky: @charlesarthur.bsky.social. Observations and links welcome.


BT agrees rescue deal to buy broadband operator TalkTalk • BBC News

Mithcell Labiak:

»

The UK’s biggest broadband provider, BT, has agreed to buy rival operator TalkTalk to save the company from collapse.

The takeover would end of months of speculation over the future of TalkTalk and mean services for its millions of customers will continue as normal. BT boss Alison Kirkby said it provided “a safety net” for TalkTalk customers. The administrator, Alvarez & Marsal, said it also provided certainty for TalkTalk’s 900 staff based in Salford, Greater Manchester.

However, Virgin Media called it a “stitch-up” which allows BT to “tighten its grip” over the market. The government has given itself the power to have the final say on the deal, citing its importance to vital public services. TalkTalk has 1.5 million retail customers and one million wholesale customers across the UK.

BT’s Kirkby told the BBC’s Today programme: “Two and a half million customers, including vulnerable households, and key emergency services might have lost their services if Talk Talk had failed, which it was on track to do. So BT stepped in as we were the only viable option to take the business forward.”

…TalkTalk began as a challenger to BT in the broadband market. It was listed on the London Stock Exchange, but was taken over by private equity in 2021. [In fact: taken private by its founder and others – Overspill Ed.] Since then, the firm has built up debt while losing customers, leaving it unable to pay some of those it owes money to.

Despite this, TalkTalk remained the fourth biggest broadband provider in the UK, with 6.6% of customers, during the March to June period of this year, according to figures from analytic firm Opensignal. BT has 32.5% of customers, Sky 19.9%, and Virgin Media 19.1%.

Rivals who were beaten to the deal by BT have said it will be bad for consumers. Tom O’Hagan, a former TalkTalk executive who was leading a takeover bid for the firm, told the BBC he was worried about “reduced choice and potentially an increase in price for consumers and for businesses” because of the BT deal. He added that he was particularly concerned about competition in the wholesale market, where TalkTalk’s subsidiary PXC was BT’s main rival.

Virgin Media, which has also reportedly tried to buy TalkTalk in the past, said the BT takeover has “all the characteristics of a stitch-up masked as a rescue deal in the public interest”.

«

The quiet collapse of TalkTalk had completely passed me by. But why has Lisa Nandy approved BT rather than Virgin or Sky, the two smallest, to buy it? Was Virgin’s price so wrong? This entrenches the largest company which also has control of the network provision – taking us back to the time before TalkTalk existed. Another great piece of work by Nandy, who rivals chocolate teapots for usefulness.
unique link to this extract


Siberian anti-plague institute staff isolated after worker’s death • Radio Free Europe/Radio Liberty (RFE/RL)

RFE/RL’s Siberia.Realities and Alex Raufoglu:

»

More than 60 staff at a Russian plague research facility have been isolated following the death of a laboratory worker, sources told RFE/RL’s Siberia.Realities, and the United States said it was monitoring reports of a suspected case of pneumonic plague.

Darya Shipilova, a 28-year-old laboratory technician at the Irkutsk Anti-Plague Research Institute of Siberia and the Far East, was hospitalized on September 29 and died at a hospital early on October 2, according to news reports and sources.

Independent Siberian news outlet Lyudi Baikala (People of Baikal) reported that Shipilova accidentally broke a test tube containing pneumonic-plague bacteria on September 25 while working at the institute. Russian authorities have not publicly confirmed that account.

Rospotrebnadzor, Russia’s consumer and public-health watchdog, said Shipilova had been diagnosed with “pneumonia of unknown etiology,” meaning that its cause was unknown. The agency said additional testing was conducted because of her professional activities but did not detect microorganisms associated with her work.

Rospotrebnadzor also said no accidents involving pathogenic microorganisms had been recorded at the institute.

…In a Telegram post on October 5, regional Governor Igor Kobzev said the “sanitary and epidemiological situation in Irkutsk” and the nearby district where Shipilova had been hospitalized “is currently stable.” He added that no new cases of institute employees seeking medical care had been reported in recent days.

«

OK, it’s just about possible that Shipilova caught pneumonic plague from a wild animal. But you’d really look to Occam’s Razor to tell you that it’s more likely she was involved in a lab accident. (This reads across oddly to Covid, of course.) Seems like the Russians have already got their own watching brief going on this one.
unique link to this extract


AI glasses face their first major government crackdown • Financial Times via Ars Technica

Richard Milne:

»

Norway has become the first major country to propose a temporary ban on the use of AI glasses in selected public places amid growing privacy concerns over wearable technology.

The rich Scandinavian country’s centre-left government said on Monday that it would introduce a law to parliament soon on a temporary ban for places such as parks, beaches, schools, and kindergartens. It will also set up an expert group to propose permanent national rules.

“I am concerned about the introduction of powerful new technology where people risk being photographed, filmed, or recorded without their knowledge,” said Torgeir Micaelsen, Norway’s digitalization minister. A temporary ban “will give us time to conduct a thorough assessment and hold an informed debate that can lay the foundation for permanent regulation,” he said.

Governments around the world are grappling with how to regulate AI glasses—including those from Facebook owner Meta and cheaper copycat devices—amid worries that they are being used to film people without their consent, including children and women in settings such as changing rooms.

Parts of Norwegian society have already reacted with their own bans, including schools in the capital Oslo and the country’s biggest company, oil and gas major Equinor, which has banned them from its offices and offshore facilities.

«

Very rare for a government to get out ahead of (or level with) a new technology; bravo Norway for at least bringing it up.
unique link to this extract


Micron CEO says memory supply will be much tighter in 2027 and 2028 than in 2026 • TechPowerUp

Usman Saleem:

»

Micron CEO Sanjay Mehrotra says memory and storage supply will likely be much tighter in 2027 and 2028 than it was in 2026. He made the remarks during Micron’s fiscal Q4 2026 earnings call on September 30, where the company reported record quarterly revenue of $54.2bn. Here’s what he said:

“Industry demand has strengthened since our last earnings call, and we expect memory and storage supply-demand conditions to be much tighter in fiscal 2027 and 2028 than they were in 2026. AI is becoming super intelligent, and memory enhances this intelligence and the competitiveness of our customers’ platforms. Even with additional industry DRAM clean room space plans with robust demand trends, including new upside requests from customers, we do not have line of sight to when supply and demand will return to balance.”

In June, Micron CEO said they expected industry supply to improve gradually in 2028, but couldn’t predict when supply would catch up with demand. The company now says it still has no line of sight to a balance, even with additional industry cleanroom space planned.

New capacity takes time as well, since Micron’s Idaho ID2 fab is only expected to start wafer output in late 2028. Mehrotra also said more than 75% of Micron’s 2027 output is already committed to customers. On the consumer side, Micron said DRAM prices rose in the high-teens% range last quarter, with NAND up about 30%.

«

Well, that’s the PC and (to a lesser extent smartphone) businesses screwed for the foreseeable, then.
unique link to this extract


Webster man celebrating the 100th birthday of the kidney his mom donated to him as a teenager • WHEC.com

Jennifer Lewke:

»

A Webster man is celebrating the 100th birthday of the kidney his mom donated to him as a teenager.  In March 1978, surgeons at Strong Hospital transplanted a kidney into 16-year-old Ray Vetuskey.  The story behind that kidney is now one for the record books. 

Vetuskey grew up in Seabreeze as the youngest of five kids and always had a special bond with his mom Betty, “she was a great lady; everyone loved her in the neighborhood,” Vetuskey recalls.

When he was a teenager, Vetuskey started having health issues and doctors ran several tests. “They told the doctors that the kidneys aren’t working and put me on dialysis,” Vetuskey says. The dialysis did not help; his kidneys didn’t recover and the only option was a transplant. 

Betty Vetuskey, who was 52 years old at the time, offered one of her kidneys to her son. “I don’t think she gave it two thoughts, anything she could do to help her son, I think she would have done anything which she did in my eyes,” Vetuskey remembers. 

Vetuskey still has his calendar from March 1978, with the date of his surgery circled along with another date for a Genesis concert. “We were both on the gurneys, holding hands and mom was crying and said don’t worry about a thing because I got a concert to go to and I’m not going to miss it,” he says with a laugh.

The transplant was a success and Vetuskey made it to the concert, “I have the ticket still, I have the ticket stub still,” he says.

Forty-eight years later, Betty’s kidney is still working for her son, making him the longest surviving kidney transplant recipient in Strong Hospital’s history.

…A living kidney donation typically lasts 15 to 20 years. “The special connection, biologically it’s important as well as mom and son sharing a lot of DNA but also emotionally that’s a different connection,” Dr. Molnar says.

«

This seems like a much more interesting story than just being an anniversary. Is the DNA similarity why this kidney survived so well?
unique link to this extract


So you think you could be an electrician? • Asterisk

Jesse Smith:

»

When I was 20, I broke both my heels in a construction accident. The right one was surgically reassembled using four heel fragments and extra bone from my hip. Workplace accidents seem to have worse outcomes than similar accidents occurring elsewhere, and at the time this specific injury had a generally poor prognosis, so doctors were initially uncertain whether I’d be permanently disabled.

When I think about my teenage son or daughter working in construction, my mind often goes to The Accident. I picture my daughter, who’s three years younger than I was at the time, wheeling to The Beer Store in a Workers’ Comp rental wheelchair each day, and coming home to down 12-pack of Molson Canadian. Or I think of my son sleeping with a fan every night to overpower the ringing in his ears. Over enough time, physical jobs exact a physical toll that desk jobs largely avoid.

Most white-collar professions have a trivially small risk of death. Even in gray-collar jobs that are widely perceived as dangerous, such as policing, most workplace deaths are caused by motor vehicles. But some trades jobs carry a risk of death or serious injury connected to specific and inherent job demands. That is, something that seems dangerous that you often do is the most likely to harm or kill you.

Jobs performed at heights, such as ironwork or roofing, have a high mortality due to falling. Electrical linesmen tend to be killed by electrocution. Arborists can be killed in a variety of ways: falling from heights, being struck by trees or electrocuted. For people in these jobs, these risks are widely understood and accepted. Almost every tradesperson knows someone who’s had at least one protracted absence due to a work injury, and many of us know someone who was permanently disabled or killed. These risks are probably less salient for people who have worked mainly white-collar jobs and know few people employed in dangerous professions.

«

Easily overlooked but undoubtedly true.
unique link to this extract


What’s the future for pure math research in the age of AI? • Stephen Wolfram Writings

Stephen Wolfram (you know, one of the guys who produced Mathematica in 1988):

»

We’ll talk later about the general character and value of pure mathematics. But before that, let’s address the issue of the moment: the role of modern AI.

And the first thing to say is that it’s unquestionably useful, sometimes very useful. For me, its greatest use in mathematical pursuits has been its ability in effect to thematically mine the knowledgebase of human mathematics. Starting back in the 1970s, being able to do keyword searches of the scientific literature was a crucial enabler of quite a bit of the research that I did. And now, with modern AI, one can do so much more. Because somewhere inside those LLMs—in a way that we don’t yet scientifically understand—there’s what amounts to a representation of raw ideas gleaned from all those millions of papers and books about mathematics.

And, at its best, it’s not just about retrieving things. It’s also about making connections. Of being able to see that this result here can be put together with that result there to come up with a surprising and useful conclusion. Humans routinely do that too. But they tend to have only read hundreds of papers; AIs have effectively read millions, and it’s cheap for them in effect to try out lots and lots of possible combinations.
So can one expect to just launch an AI off and have it come back with great math? As we’ll discuss, great math is—more than anything else—defined by the questions it asks. Yes, the AI can successfully automate things that humans would normally have had to do themselves before. But—as we’ll discuss later—at the core of pure mathematics is the human imagination that guides what questions to ask.

It’s worth understanding the difference between what modern AI does, and what pure computation does. Modern AI is, first and foremost, a way of leveraging the existing corpus of human knowledge. Computation is—at its most powerful—an open-ended way to generate things that are fundamentally and irreducibly new. Start from some rule or axiom, and just repeatedly run the computation of applying it, and my all-time favorite phenomenon of computational irreducibility guarantees that you’ll go on getting fresh, new results that can’t be reached except by doing all those computational steps.

…So, yes, having nothing to do with AI, computation can generate an infinite sequence of new theorems, representing an infinite sequence of new facts, etc. And among those theorems there’ll be all sorts of “originality” and, in effect, “surprise”. But there’s a catch. Those theorems are in a sense just “results plucked from the computational universe”. And as such they certainly fall under the purview of the new—and I think very important—field of ruliology on which I have spent so much effort. But are they math?

«

Wolfram is one of those people who, when they speak, deserves hearing.
unique link to this extract


OpenAI “rogue” agent activities found on Wikimedia projects • Wikimedia

Selena Deckelmann:

»

The Wikimedia Foundation conducted its own investigation to see whether Wikimedia websites had been similarly affected by AI agents, focusing on those operated by OpenAI. We can confirm that we have discovered some activity by these “rogue” OpenAI agents on Wikimedia platforms. The unauthorized bot activities included edits to our wikis, some unsuccessful attempts to exploit a public note-taking tool we host, and heavy traffic, which are described more below.

We did not find any evidence that our systems were used for coordination among agents, nor did we find any evidence of our systems or data being compromised. However, we are concerned about what could have occurred here, the difficulty and effort involved in investigating and attributing this activity, and the growing risks of agentic AI activity on our platforms in general. The open web is a public good. We should not allow this behavior to become the “new normal” for the people or organizations that maintain it.

…Wikipedia was designed for humans – and agentic behavior clearly poses challenges that no one has solutions for. Because of our unique and successful knowledge creation model, Wikimedia’s volunteers are the ones who come in first contact with, and clean up the mess left behind by AI agents. Rising bot traffic and agentic activity is showing a real impact on the Wikimedia projects and the infrastructure that makes it available for millions of users globally. In 2025, the Foundation reported that its bandwidth usage had increased by 50% due to the surge of bot activity on its websites since 2024. At the same time, 65% of the most resource-consuming traffic on its projects was coming from bots.

«

A lot of the edits and accesses were trying to use Wikimedia resources to access other sites. But you can see how the demand would grow and grow. This ins’t going to be sustainable in the medium or long term.

unique link to this extract


arXiv is rate limiting submissions because it can’t keep up with AI slop • 404 Media

Matthew Gault:

»

arXiv, an open-access repository where researchers publish preprint academic research, has announced it will rate limit submissions because it has been inundated with AI-written papers. A researcher can now only send in two pieces per calendar month and have a total of three active submissions at any given time. In a blog post about the change, arXiv said AI has made it too easy to spam the publisher’s inbox and its volunteer moderation team is overwhelmed.

“The heart of arXiv’s process for detecting and rejecting low-quality papers is our many volunteer moderators,” Thomas Dietterich, an Oregon State University professor emeritus and the chair of arXiv’s editorial advisory council said in a statement. “We are so grateful that they donate their time and expertise every day. However, a relatively small proportion of authors are submitting a large number of low-quality papers and consuming a disproportionate fraction of the moderators’ time. This is unfair to authors who continue to submit quality papers — their papers can be delayed for days or weeks as a result.”

According to arXiv, it received 9,869 submissions in September 2016, 20,569 submissions in September 2024, and 40,363 submissions in September 2026. Submissions on the site have doubled in the last two years and have sextupled in the computer science category.

AI is driving this surge in multiple ways. Researchers are using LLM to parse massive data sets, write code, and design portions of experiments; some are also using AI to write the papers.

«

unique link to this extract


Pure ICE cars fall below 50% of global sales for the first time • Electrek

Fred Lambert:

»

Gas cars are now a minority of the world’s new car sales. Gasoline-only vehicles made up 49% of global new-vehicle sales in the first half of 2026, down from 73% in 2021, according to Mobility Global data first reported by Nikkei.

It’s the first time on record that they’ve been under half. But there’s a catch: most of the cars taking their place still have a gas tank.

Mobility Global is the auto data firm formerly known as S&P Global Mobility, which was spun off from S&P Global this year. Nikkei reported its first-half numbers last week, and they show sales of gasoline-only cars down 10% from a year ago to 20.25m units between January and June.

Their share fell three points in a single year, from 52% to 49%.

Battery-electric vehicles grew 12% to 6.87m units and took 17% of the market, up three points. Conventional hybrids grew 10% to 7.27m units, or 18%.

…Nikkei ties the acceleration to oil. Fuel prices spiked with the conflict in the Middle East, and buyers went looking for lower running costs.

The whole car market shrank about 5% in the first half, according to the IEA, so gas-only sales fell twice as fast as the market.

«

A tipping point? There are still problems with home charging, which is the ideal.
unique link to this extract


• Why do social networks drive us a little mad?
• Why does angry content seem to dominate what we see?
• How much of a role do algorithms play in affecting what we see and do online?
• What can we do about it?
• Did Facebook have any inkling of what was coming in Myanmar in 2016?

Read Social Warming, my latest book, and find answers – and more.


Errata, corrigenda and ai no corrida: none notified
Start Up No.2755: another OpenAI safety staffer quits, F1 stalled by software bugs, Meta wants to infuse Muse, nine albums?, and more


Despite what you think you know, landfill is actually a better option for waste disposal than many others. CC-licensed photo by Elliott Brown on Flickr.

You can sign up to receive each day’s Start Up post by email. You’ll need to click a confirmation link, so no spam.

A selection of 9 links for you. Filling up. I’m @charlesarthur on Twitter. On Threads: charles_arthur. On Mastodon: https://newsie.social/@charlesarthur. On Bluesky: @charlesarthur.bsky.social. Observations and links welcome.


US arrests tech CEO accused of smuggling $300m in Nvidia chips into China • Ars Technica

Ashley Belanger:

»

The US has arrested another suspect accused of smuggling high-end computer servers containing export-controlled Nvidia chips into China.

In a press release on Thursday, the Department of Justice accused 38-year-old Greg Lui of using false paperwork to mask shipments of servers worth more than $300m that he allegedly knew were ultimately destined for China.

As the CEO of Earthmade Computer, Lui allegedly conspired with freight-forwarding firms in South Asian countries like Malaysia and Singapore to illegally divert chip shipments into China, including Nvidia’s A100 GPUs and H100 GPUs, the FBI’s indictment alleged. These are not Nvidia’s most advanced chips. However, the chips can process large amounts of data and train large language models, which the US fears could pose national security risks if China suddenly gets access to enough chips to drastically advance its AI or strengthen its military.

Emails and bank records exposed the smuggling scheme, the DOJ alleged, which started in October 2023 and continued until August 2026.

One key piece of evidence is a 2024 email discussing an order for 70 servers with export-restricted GPUs that were fraudulently claimed as destined for Malaysia. After “Lui submitted a purchase order to a US manufacturer for 27 of these servers for approximately $7,614,000,” the DOJ alleged that a co-conspirator told a Malaysian government official that all 27 were shipped to China.

A similar shipment of 92 export-controlled servers was allegedly routed through Singapore to Malaysia, then Hong Kong. Finally, the chips went to a Chinese firm based in Hangzhou, the FBI alleged, which The Wall Street Journal last year described as China’s AI hub.

«

It’s the new arms trading!
unique link to this extract


I quit OpenAI because its culture is broken • The Atlantic

David Robinson:

»

What I’m about to tell you has, I realize, become something of a cliché: I resigned this week from OpenAI. I led the writing of the safety reports we published with each major launch. Now I’m joining a parade of former colleagues—at OpenAI and the industry’s other leaders—who have decided that the current path is unacceptable.

I agree with other recently departed staff that the companies building this technology aren’t being nearly careful enough. But I believe that we need to look deeper than specific rules or new laws. We need to talk about culture.

The future depends on wisdom that Silicon Valley lacks. Wisdom about how to handle dangerous technology and, more fundamentally, wisdom about what it means to care for people. This moment needs a degree of humility that isn’t natural for people who have succeeded through their extreme confidence. My former colleagues at OpenAI were prescient: They came to understand the scaling laws that meant bigger AI systems would be smarter—and so they went all in on building bigger systems, at great cost. A can-do attitude of achieving the seemingly impossible—coupled with work timelines that amount to perpetual sprints—are common across the industry.

…This summer, in the Hugging Face incident, OpenAI let a swarm of agents out by mistake. The company responded by making security improvements. But even after those changes, OpenAI reported that its safety controls failed again, when a model in training bypassed restrictions on internet access: A monitoring system alerted human staff but did not automatically turn the model off as it was supposed to. Anthropic, too, has acknowledged accidentally turning off its own safeguards because of a misconfiguration. I believe that such mistakes are typical of the industry, given the speed and flexibility with which people operate.

…Two changes are urgently needed. First: AI companies need to rely more on the safety expertise that already exists in other fields. And second, before we create systems significantly more capable than the ones we have today, we need new science to ensure that more capable models (and their successors) will make safe choices when we aren’t looking.

Given today’s risks, frontier labs need to run like nuclear-power plants or busy airports, with layers of redundancy and careful, time-consuming planning, so that the occasional and inevitable human error does not open a door to disaster.

«

(Gift link.)
unique link to this extract


How computer software bugs led to F1’s Malaysia farce: “totally unacceptable” • The Athletic

Luke Smith:

»

A heavy shower just before the cars went to the grid prompted the race director to sensibly delay the start. After 40 minutes, once the rain eased sufficiently, a call was made to get going, with a damp track offering the first wet racing of the year.

Max Verstappen led the field away behind the safety car, ready to discover how these all-new cars would perform in the rain. After two formation laps, they would line up on the grid and get racing. Until they couldn’t.

First it was [Max] Verstappen, reporting he was pushing down on the accelerator and feeling nothing, causing him to slow. Then Lewis Hamilton. Then Nico Hülkenberg, Esteban Ocon, Ollie Bearman, Sergio Pérez, all coming to a crawl. One by one, the same problem emerging. Amid the uncertainty, cars around them slowed down to avoid overtaking and a possible breach of the rules.

…The total confusion left race control with no decision but to abandon the plan to get started and return the cars to the pit lane, now in a jumbled-up order. It led to another, longer wait to get going.

The reason for the wait? The FIA, motorsports’ governing body, had to issue a software update for all the teams to install on their cars to fix the computer algorithm that controls the engine and prevent the issue from repeating after a bug had emerged. By the time the race finally began on a considerably drier track, more than 90 minutes had passed since the scheduled 3 p.m. start time.

This season’s all-new engines rely heavily on the software to manage when power is delivered by the battery, which is responsible for almost half of the total power output.

Drivers have complained regularly through this season about how difficult it is to trust the energy deployment at times, with changes from lap to lap. The complexity of the engines has made them hard to understand and created cars that are unnatural to drive. Verstappen referred to F1’s 2026 rules as “anti-racing” back in February.

In Malaysia, that same complexity reared its head in frustrating fashion.

Mercedes and Honda engines were unaffected, but the bug, previously unidentified in the limited wet-weather testing conducted with these cars, left many drivers frustrated.

“It’s obviously not great what happened,” said Pérez, who said his car felt like a rental go-kart. “I’m sure we will learn from it, but what happened today is totally unacceptable for the sport.”

«

unique link to this extract


Analysis: wind and solar save UK from gas imports worth £5.9bn during Hormuz crisis • Carbon Brief

Simon Evans and Ho Woo Nam:

»

The UK has avoided the need for gas imports worth £5.9bn since the start of the Hormuz crisis as a result of record generation from wind and solar, reveals Carbon Brief analysis.

While gas prices are surging to levels not seen since the 2022 energy crisis, the UK has been generating record amounts of power from wind and solar, up 14% year-on-year.

This unprecedented clean-power generation is directly cutting the need for gas-fired electricity, which is down by nearly 10% year-on-year in 2026 to date. In total, wind and solar have generated a record 41% share of the UK’s electricity needs in 2026 to date, compared with 25% from gas, according to Carbon Brief’s analysis.

Wind and solar has avoided the need for UK gas imports worth £5.9bn, since the outbreak of war between the US and Iran in February 2026. These avoided gas imports would have required the UK to secure the equivalent of more than 100 additional tanker deliveries of liquefied natural gas (LNG).

…From this Thursday, 1 October, typical household gas bills will be 33% higher than they were in April, some £200 per year, according to thinktank Nesta. By contrast, household electricity bills will only have risen 4%, according to Nesta’s analysis, as a result of growing generation from clean-energy sources.

Andrew Sissons, director for sustainable future at Nesta, explained in a social media post that “the link between electricity and gas prices has already begun to break”.

«

Would have been useful to know how many LNG tankers came in over that period. Are we talking about a 1%, 10%, 40% reduction? Also: a typical 15,600 cubic metre LNG tanker can carry cargo worth about $2m, but the “100 tankers avoided” equation suggests the cargo is worth $59m. Anyway: it’s a lot.
unique link to this extract


Just bury your trash • Works In Progress

Alex Chalmers and Rob Wiblin:

»

The case against landfill has two parts. The first part is that there are efficient, cheap, or environmentally friendly ways to practically reuse or recycle materials, rather than landfilling, meaning that there is a reasonable alternative. The second is that landfill itself is unsustainable, or environmentally unfriendly, meaning that we need an alternative. Both are false.

It’s natural to assume that reusable always means better. But this intuition treats different materials as interchangeable and ignores the cost of making them in the first place. Once we account for energy, labor, and other inputs, reuse pays off only in selective cases.

Producing tiny slivers of plastic uses almost no energy. Making the polyethylene resin for a single thin plastic bag, then blowing and sealing it, uses something like 0.6 megajoules, roughly the same energy as boiling a kettle of water. By contrast, cotton is extremely energy intensive, partly because cotton bags need to be much thicker to work, and weigh around 200g as compared to 8g for polyethylene. Instead of a simple blowing and sealing process, the cotton must be made into yarn, woven into fabric, prepared, dried, sized, dyed, and finished, which takes around 17.5 megajoules, around 29 times as much energy.

In total, Britain’s Environment Agency calculated that a conventional cotton bag needed to be reused 173 times to beat plastic. Denmark’s equivalent public body estimated a similar ratio. Sufficiently well-worn cotton tote bags can beat plastic for environmental cost, but only for the most consistent among us.

The same pattern shows up almost everywhere we have tried to replace disposable goods with durable ones. Steel is more energy intensive than plastic, and a steel straw requires 10g of steel, compared to just 0.2g of plastic for a plastic straw. So even if the steel is never washed (hot water is also energy intensive), it would take 150 reuses for a steel straw to use fewer resources than a plastic one. And who would go without washing it?

A ceramic mug only beats a polystyrene cup on energy use after 1,000 uses, and even then only if your dishwasher is fairly efficient. Run a less efficient one and the disposable cup wins on energy forever. Cloth diapers feel greener than disposables, but once you account for the cotton, the laundering, the hot water, and the detergent, the UK Environment Agency found the two are roughly tied in overall demand on resources. A returnable milk bottle takes much more energy to produce and much more fuel to transport than a plastic carton, and has to make around ten or more trips to use less energy than a bottle made from polyethylene plastic.

«

But, you object (I did), all that plastic is thrown away and pollutes places, surely? No:

»

Richer countries have near-universal refuse collection and almost none of their waste winds up in the ocean. In low-income countries, however, over 90% of waste is improperly managed, and typically ends up dumped, burned, or escaping into waterways. Plastic flows into the ocean overwhelmingly come from a small handful of rapidly growing Asian economies. Approximately a hundred rivers, mostly in South and South-East Asia, account for half of ocean plastic. And a substantial share of plastic in the ocean isn’t domestic waste at all, but rather discarded fishing gear.

«

There’s more, too, about how modern (properly managed) landfills work.
unique link to this extract


Meta wants your next gadget to be Muse-infused • TechCrunch

Kirsten Korosec:

»

Meta’s Muse, a personal AI agent that books travel, fills out forms, and shops on a user’s behalf, has already proven popular with the masses, but a new side project could be particularly alluring to tinkerers and hackers.

On Friday, the company introduced Muse Gadgets, an open-source project that lets developers build their own hardware that connects to Muse.

Meta is providing open-source firmware (the low-level software that runs a device), and a Linux software development kit (SDK), along with a few project ideas to get users started. These include giving Muse a color e-ink display or loading it onto a stick that plugs into a TV’s HDMI port.

There don’t appear to be many limits, either. Users can set up a low-cost hobbyist computer like a Raspberry Pi or an off-the-shelf ESP32 board, and then connect Muse “to your displays, buttons, sensors, actuators, and whatever else you’ve got lying on your workbench,” Meta notes.

The company has also set up a Discord channel to support users.

Meta has already tried the code itself, naturally. Nat Friedman, head of product at Meta’s Superintelligence Labs, said in a post on X that the company built a gadget called Muse Home Link. The USB-C-powered device lets Muse connect to a home network and talk to the smart devices on it, including speakers and smart TVs.

Meta made 5,000 of these Home Links, in fact, and is giving them away for free to Muse subscribers while supplies last, according to Friedman. Considering Friedman’s post about Home Link received nearly 30,000 views in a few hours, we’re guessing those freebies have been claimed. Friedman said Home Link would be ready to ship a few weeks.

Muse Gadgets may not have wide appeal, but it fits nicely into Meta’s all-in strategy to make Muse more than a standalone chatbot. Meta isn’t content to push Muse on everyday consumers; it’s also trying to woo small businesses and enterprises.

«

Clever little Trojan Horse strategy they’ve got going on there.
unique link to this extract


my9albums: pick the 9 albums that made you

Nahue Alberti:

»

Pick the 9 albums that made you.

Search more than two million albums, put your nine in order, and share the poster.

«

Fun little distraction which has shown us how disparate people’s music tastes can be. (Also that post-2006 or so it’s difficult to think of things in terms of albums.)
unique link to this extract


Things that apparently cause cancer • Breakthrough Journal

Deric Tilson and Adam Stein:

»

It would shock you to know that Costco, according to a new Harvard School of Public Health methodology, caused 120,687 cases of cancer mortality nationally every year, simply due to living in close proximity to their warehouses. Private colleges accounted for 83,782 more. Harvard itself is responsible for 5,842 cancer deaths. Living near a Major League Baseball field causes almost 19 times as many cancer deaths as living near a Major League Soccer pitch. These conclusions are obviously absurd, but they come from the exact same methodology that researchers at Harvard use to “prove” that nuclear power plants cause cancer in nearby communities.

Earlier this year, Adam Stein and I called out a series of Harvard studies showing that nuclear power plants were associated with higher rates of cancer incidence and cancer mortality as nonsense. Now that we’ve spent the last few months replicating the analysis and expanding it, we are able to show that no matter what landmark you use, their methodology will show an increased cancer risk and mortality. The studies simply do not prove anything about cancer incidence.

…The papers construct a “proximity score” based on distance from nuclear plants, up to 120 km in Massachusetts and 200 km in the national studies (about 75 and 125 miles). Every ZIP code or county inside those radii is treated as exposed, with closer locations receiving higher weights. If a ZIP code or county is within range of multiple sites, then the effect is cumulative. That means that a county that is in close proximity to one nuclear power plant could have a smaller score than another county that is further away from any one power plant but within range of many.

From this proximity score, the authors run regressions testing the outcome (cancer incidence, cancer mortality, or total mortality) on the proximity of the county and a collection of covariates. From this, they use the statistical coefficients, construct the Relative Risk for each county, age, and sex group, and compute the Attributable Fraction, from which they derive the number of attributed deaths from the nuclear power plant from 2000 to 2018.

«

Basically, living near enough to any object “causes cancer”, using that methodology.
unique link to this extract


FedEx believes $300m electric truck spend will save them $800m in diesel • Electrek

Jo Borrás:

»

In a record-setting commercial truck deal, international shipping giant FedEx has placed an order for 2,000 all-electric box trucks from American startup Harbinger in a deal that’s reportedly worth more than $300 million – but the ROI could be much higher.

FedEx is making serious moves to fully electrify its operating fleet by 2040, and this latest Harbinger deal is believed to be one of the largest binding orders for electric medium or heavy-duty trucks in history. It’s certainly Harbinger’s largest order, at least.

…Harbinger estimates that each of the electric Class 5 and 6 medium-duty box trucks delivered will reduce FedEx’ fuel costs by around $20,000 annually compared with the conventional diesel-powered vehicle they replace. Additionally, Harbinger says its vehicles are designed for a functional service life of 20 years.

2,000 trucks x $20,000 in fuel savings per year x 20 years. That works out to $800m in total savings, for a whopping ~166% ROI.

“Electrifying a fleet at this scale requires vehicles that can perform the work our robust operations demand while also delivering meaningful economic benefits,” said Paul Melander, Senior Vice President Safety & Transportation, FedEx and member of Harbinger’s Board of Directors. “Expanding our deployment of Harbinger vehicles gives us an opportunity to continue making progress toward our fleet electrification goals while reducing fuel and operating costs.”

Saving money is great, but the much more important issue for you and me is that the move to Harbinger electric trucks will help FedEx avoid more than 1.7m tons of CO2 emissions over their projected operating lives.

«

unique link to this extract


• Why do social networks drive us a little mad?
• Why does angry content seem to dominate what we see?
• How much of a role do algorithms play in affecting what we see and do online?
• What can we do about it?
• Did Facebook have any inkling of what was coming in Myanmar in 2016?

Read Social Warming, my latest book, and find answers – and more.


Errata, corrigenda and ai no corrida: none notified
Start Up No.2754: Meta’s data centre tax tricks, AI Overviews evade antitrust, Swiss glacier melt speeds up, RIP SMRs?, and more


A diesel export ban by the US would have limited benefit because it would quickly suppress refinery production of other fuels too. CC-licensed photo by Geekly Things on Flickr.

You can sign up to receive each day’s Start Up post by email. You’ll need to click a confirmation link, so no spam.


A selection of 11 links for you. Cracking up. I’m @charlesarthur on Twitter. On Threads: charles_arthur. On Mastodon: https://newsie.social/@charlesarthur. On Bluesky: @charlesarthur.bsky.social. Observations and links welcome.


How Meta uses AI data centres to avoid billions in federal taxes • The New York Times

Kashmir Hill, Jesse Drucker, Eli Tan and Mike Isaac:

»

Mark Zuckerberg says Meta’s A.I. push is a tremendous success. “Our investments in AI are accelerating every major part of our core business,” he has told investors. “Every sign that we’re seeing in our own work and across the industry gives us confidence in this investment.”

But when Meta files its taxes, it tells the Internal Revenue Service (IRS) a different story. It claims that its AI data centres are a giant experiment that could fail, according to four people with knowledge of the company’s operations.

It does this so it can tap into a tax credit intended for research and experimentation. It’s an aggressive interpretation of the tax break, which Meta embraced to claim billions of dollars in tax credits for data centre expansion.

Characterizing its AI data centres as experimental is “kind of wild and out there,” said Andre Shevchuck, a partner at the advisory firm BPM who specializes in the research and experimentation tax credit.

Indeed, Meta’s own accountants recognize that the strategy is on shaky legal ground. In disclosures buried in securities filings, the tech giant warns that billions in tax savings are vulnerable to being overturned by the IRS, in large part because of “uncertainties with our research tax credits.”

Here’s what Meta is doing: for tax purposes, the company classifies its enormous, multibillion-dollar data centres as “pilot models.” Under a tax credit created in the 1980s to spur innovation, companies can get a rebate for supplies, but only if they are being tested in an experimental effort, not standard business operations. Meta is claiming that the costly AI computer chips it buys from companies, including Nvidia, are entitled to a taxpayer-provided discount as part of the experiment.

…Meta is already in one sizable dispute with the IRS over this tax break, for using it to subsidize its chief executive’s multibillion-dollar pay package. In 2013, Meta claimed that $4.1bn of stock options exercised by Mr. Zuckerberg counted as a research expense because he helped invent new software, such as Facebook’s News Feed. The IRS is trying to claw back the company’s resulting $355m in tax savings, court filings show.

«

The data centre finagle is estimated to have saved it $4bn on its tax bill last year. The “research expense” wrinkle is surely what Meta pays its tax lawyers the big bucks for.
unique link to this extract


Google wins dismissal of Chegg, Penske Media lawsuits over AI overviews • Reuters

Mike Scarcella:

»

Alphabet’s Google has persuaded a US federal judge to dismiss lawsuits from education technology company Chegg and Rolling Stone publisher Penske Media Corp that alleged ​the search engine giant unlawfully used their content in AI-generated summaries that draw readers away from their websites.

In his ruling, opens new tab on Wednesday, US District Judge Amit Mehta in Washington said Chegg and Penske’s claims that Google’s business practices violate antitrust law “fail to get out of the starting gate.”

The companies ​said in lawsuits filed last year that Google broke antitrust law by forcing ​publishers to allow AI overviews of their content if they want to remain indexed in Google’s search results. They alleged they lost revenue from reduced traffic ​to their sites.

“Plaintiffs have pleaded only that they have an ‘expectation’ that Google will send them search ​traffic if they make their content available for free,” Mehta wrote. “But an expectation is not an agreement. It is simply how a general search engine works.”

Chegg and Penske, which also publishes Billboard and Variety ​magazines, did not immediately respond to requests for comment. Google also did not immediately respond ​to a request for comment. Google has denied any wrongdoing.

The plaintiffs said in a competitive market Google would pay them for republishing their work or using their content to train its AI systems. Google countered that it has no obligation to index publishers’ content on their preferred terms.

Mehta said he is not “unsympathetic” to the situation of publishers and other online creators whose content Google takes and repurposes ​without compensation.” But ​he said antitrust laws don’t substitute for legislators’ power to address how innovation may cause economic harm.

The judge in March rejected similar claims by a publisher ​suing Google.

«

unique link to this extract


Google’s early attempt to pay websites for AI answers is struggling • Ars Technica

Ryan Whitwam:

»

Google’s shift to AI-powered search has upended the way the world’s largest search engine generates web traffic, rankling large and small publishers alike. In recent months, the company has experimented with paying publishers when their content appears in AI answers, but a new report claims the payouts in this pilot program are miniscule. That has publishers in the program, as well as those watching from the sidelines, feeling skeptical.

According to The Information, Google has admitted about 100 publishers to the AI contribution pilot. The pitch is that websites can get payments from Google when their content materially contributes to Gemini-powered search results like an AI Overview. Google has long resisted the idea of direct payments to publishers, arguing that websites get traffic in exchange for allowing Google bots to scrape their content for use in search and knowledge graph tools. In the age of AI, that relationship is breaking down, hence the AI pilot.

So far, publishers aren’t getting much for their trouble. The Information heard from several small and mid-sized publishers in the program that Google’s AI payments are minuscule, equaling roughly one-tenth of one% of their advertising revenue. These payments have been so disappointing that several larger publishers have reportedly declined to participate in the program. These publishers hope that by refusing to join the pilot, they can force Google to offer a more generous deal.

Payments under the program vary widely, but some sites are doing well. One publisher that joined early is on track to earn more than $1m per year, a big chunk of its revenue. A more recent addition to the pilot has earned $50,000 to $60,000, which is a small slice of its earnings. Various smaller sites are seeing less than $1,000 from the program over several months, which won’t come close to offsetting declining traffic.

In general, publishers in the test seem to agree that certain topics that are not as widely covered but have strong niche interest earn more, including anime and gaming.

«

unique link to this extract


Android Central “will continue” despite laying off its staff • The Verge

Jay Peters:

»

Yesterday, four of the six staffers on Android Central’s staff page posted publicly about the layoffs, including Shruti Shekar, Derrek Lee, Harish Jonnalagadda, and Nicholas Sutrich, and former senior editor Namerah Saud Fatmi updated her LinkedIn to indicate that her tenure at Android Central had ended. Both Lee, the site’s managing editor, and Sutrich confirmed that all remaining staff were laid off.

The former staffers weren’t told whether the site would shut down. Today, new posts have been published to the site, though are from the site’s freelance contributors rather than the previous full-time staffers.

“Future [Publishing] will continue to publish Android Central. We’ll share further information about the future of the site in due course,” Future spokesperson Nicole Martineau tells The Verge, adding: “We will not be providing any further comment at this time.”

Android Police, another Android-focused blog, also laid off at least two staffers recently. The site currently lists an editorial team of four people.

«

The suspicion is that small tech sites which relied on advertising served to search traffic are hitting a wall. A comment I saw was that any site which doesn’t have lots of email subscribers for a newsletter is screwed in the world of Google’s AI Overviews. And, possibly, there isn’t the interest in the narrow topic of Doing Stuff on Android Phones as there used to be.
unique link to this extract


“Explosion of melt rates”: 20% of Swiss glaciers lost in five years • The Guardian

Ajit Niranjan:

»

Switzerland has lost almost one-fifth of its ice in just five years, research has found, in a dramatic reshaping of the Alpine country whose big white glaciers have been reduced to moonlike rock deserts, scientists say.

Swiss glaciers shrank by 5.5% in the first eight months of 2026, according to an annual monitoring report, after a summer of scorching heatwaves that followed a winter with little snow. The reduction in ice volume falls just shy of the record set in 2022 and brings the total loss of glacier ice since 2021 to 19.4%.

Matthias Huss, a glaciologist at ETH Zürich and lead author of the report, said many people do not realise how fast glaciers are retreating, or that just one generation ago some now-barren sites used to sit beneath hundreds of metres of ice. The scientists have not yet compiled a formal tally of lost glaciers this year but said they had witnessed the death of a number of small ones.

“I visited one last week and it’s so impressive to stand in this moonlike landscape where there was a big layer of ice – an extensive glacier – just a few years ago,” said Huss. “And now it’s a rock desert where there’s some scattered blocks of old ice still lying around and melting on the hot rocks.”

The report, a collaboration between the Swiss Glacier Monitoring Network and the Swiss Commission for Cryosphere Observation, found the mean thickness of individual glaciers fell by between 2.5 metres and 4 metres in 2026. Huss said scientists were increasingly seeing glaciers collapse from the inside – the result of internal streams beneath the ice that excavate caverns – rather than simply retreating from surface heat.

«

The total glacier ice volume in Switzerland has fallen from just over 100 cubic kilometres in 1920 to just over 40 cu km now, according to the Glacier Monitoring organisation. The decrease – graphed in the story – is most marked since 1980, when it was about 90 cu km.
unique link to this extract


RIP SMRs: is it the end of the line for Small Modular Nuclear Reactors (SMRs)? • The Energy Mix

Susan O’Donnell:

»

In early September, the organization behind Canada’s push for small modular nuclear reactors (SMRs) quietly signalled their demise.

In 2016, Canadian Nuclear Laboratories President Mark Leskinski proclaimed that “SMRs can live among the annals of great Canadian innovations.” Ten years later, the organization announced the termination of its two programs to support SMR development.

During the intervening decade [pdf], the companies promoting the 10 SMR designs in Canada had either left the country, lost their proponents, filed for bankruptcy protection, or failed to secure private sector backing for their projects.

An SMR is a nuclear reactor designed to generate 300 megawatts of electricity or less, compared to Canada’s existing CANDU reactors which generate 500 megawatts or more.

Canadian Nuclear Laboratories (CNL) manages Chalk River, the federal research campus where Canada’s top nuclear researchers conceived and designed the CANDU reactor. All the power reactors operating in Canada are a similar CANDU design, and CANDUs also operate in six other countries. But the last unit to connect to an electric grid in Canada was in 1993, and CANDU exports dried up decades ago.

CNL’s idea for a transition from large CANDU reactors to smaller reactors was an attempt to reenergize a moribund domestic nuclear industry. The concept was to lower the cost of nuclear reactors by making them smaller and building multiple modular units in factories.

…One of Canadian Nuclear Laboratories’ first research collaborations for SMR fuel was with Moltex, a UK start-up company that had set up in Saint John in 2018. Moltex proposed to use plutonium to fuel an experimental “advanced” SMR it wanted to build at the Point Lepreau nuclear site on the Bay of Fundy.

Moltex lost its proponent in 2025 when New Brunswick Minister of Energy René Legacy told CBC the province was no longer willing to take on the risk of supporting first-of-a-kind experimental SMRs. A second “advanced” SMR slated for the Point Lepreau site also lost government support. At that point, the provincial and federal governments combined had spent nearly $130m on SMR activities in New Brunswick—funds that could have gone into heat pumps and energy efficiency upgrades to combat energy poverty and cut climate pollution—without attracting private sector interest.

«

unique link to this extract


Secret watermark labels proteins as “made by AI” • Nature

Elie Dolgin:

»

Proteins designed by artificial intelligence could soon carry a hidden signature of their machine-generated origins, thanks to a watermarking system described on Wednesday in Nature.

The technology, developed by researchers at Google DeepMind in London, borrows a trick that is already used to identify AI-made content across images, video, audio and text. It involves weaving a faint statistical tell into both the amino-acid sequence and 3D shape of computer-designed proteins — without noticeably compromising their function.

Known as SynthIDBio, the approach could distinguish AI-generated proteins in biological repositories from their natural counterparts, helping to preserve the integrity of databases that underpin both scientific research and biosecurity screening.

Steph Guerra, a biosecurity scholar at the non-profit research organization RAND in Washington DC, sees value in an approach that aligns interests across the life-sciences community. Watermarking can support innovation and scientific reproducibility, she says, “and, at the same time, have a security benefit”.

The catch is that this molecular stamp can be scrubbed away. Someone who wants to erase the ‘made by AI’ tag can, in many cases, run a watermarked protein through another design tool and generate a new sequence that retains the protein’s structure and function but obscures its synthetic origins.

It is therefore best viewed as one more tool in a layered framework for guarding against biological threats, says Tessa Alexanian, a biosecurity researcher formerly at the International Biosecurity and Biosafety Initiative for Science, a non-profit organization in Geneva, Switzerland. “We’re in a wild new world,” she says.

«

unique link to this extract


Breaking the Marmont Cipher, 1809 • Carter Church

Carter Church:

»

In February 1809, Vienna decided on war. Napoleon had deposed the Spanish Bourbons the previous spring and taken their kingdom for his brother, and Vienna concluded that the Habsburgs were next unless it struck while his best troops were tied down in Spain. On 8 February the Austrian Empire resolved to fight Napoleon, with the war party pointing at the French disaster at Bailén in Spain, where an entire French corps had surrendered the previous July. Archduke Charles was the Austrian Emperor’s younger brother and the best general the Habsburgs had. He had spent three years rebuilding the army: 340,000 regulars, plus a new Landwehr militia on paper at 240,000. Everyone could see what was coming.

Napoleon had a specific problem, and its name was Marmont.

Marmont, a personal friend of the Emperor, had been entrusted with what were called the “finest” troops in the theatre (about 13,000 men by Napoleon’s own count), and they were parked in Dalmatia on the far side of the Adriatic. Austrian territory sat between them and every other French army. If war came, Marmont would be the most isolated general in the Empire.

So on 16 March 1809, Napoleon wrote from Paris to his stepson Eugène, the Viceroy of Italy, and told him to send Marmont a letter. It was to lay out where every French and allied army stood. It was to go “dans une lettre chiffrée et par un officier intelligent”: in cipher, carried by an intelligent officer.

That letter, or one written to exactly that order, survives. Its first line is in plain French: Vous avez dû recevoir, Monsieur le Général Marmont, mes lettres des 8, 14 et 20 courant. [Translated: “You have already received, General Marmont, my letters of the 8th, 14th and 20th.”]

After that come twenty-four rows of two-digit numbers, stray letters, and invented symbols. The key didn’t survive, and for 217 years nobody alive could read it.

…Marmont’s own headquarters used a code of only about 150 entries in 1811, with nine different figures for E, and the British staff officer George Scovell broke it within two days, helped by the plain words Marmont’s clerks kept leaving mixed in with the cipher. Whoever wrote this letter was more careful.

…I’ve never broken a cipher.

«

And arguably Church didn’t this time either. GPT-6 (Astra) did. The cipher is, as you’d expect, pretty complex. The LLM solved it in about six hours.
unique link to this extract


Banning diesel exports won’t solve Trump’s biggest problem • The New Republic

Grace Segers:

»

The theory behind restricting or banning diesel exports is that more diesel would remain in the country, and therefore fuel costs would go down: if you ship out less, you keep in more. But the reality of that scenario would be more complicated. The US already produces around 5.3m barrels per day of distillate fuels, which include diesel, but the domestic demand is only around 3.6m barrels. Refiners on the Gulf Coast rely on trade to absorb that surplus; if exports are banned, around 1.5m barrels per day of diesel would be “stranded,” according to analysts at S&P Global.

These risks have left oil industry stakeholders in a tizzy. The American Fuel and Petrochemical Manufacturers have warned that such a ban would “reduce US fuel production, put upward pressure on prices, weaken energy security and hand market share to foreign competitors.” It’s a concern echoed by the folks at the American Petroleum Institute (API), who fear that a fuel surplus would lead to refineries producing less gasoline and jet fuel along with reducing diesel production.

The US produces diesel at a structural surplus, and there is room for refineries to stockpile diesel if it is unable to be exported. But eventually, refineries will no longer have a reason to continue processing as much crude oil.

“You are going to destroy the financial incentive to process these barrels in the first place, and these refiners will begin cutting runs,” said Johnston. S&P Global analysts predict refiners would ultimately need to cut crude runs by 1.9m barrels per day.

Commodity analysts at Goldman Sachs have predicted that an export ban would initially lead to a decrease in prices—but only until diesel storage is full. Because different fuels are produced together, such an action would put “upward pressure on gasoline prices,” according to a memo by Goldman Sachs. The bank estimated that gasoline prices could increase by $0.30 per week. [Emphasis added – Overspill Ed]

A diesel export ban would also have global repercussions. With less diesel coming from the Middle East, China, and Russia, other countries across the world have been more reliant on American oil. According to API, the US currently supplies around 20% of the roughly eight million barrels of diesel traded globally per day. Diesel prices continue to spike largely because the US is the primary source for buyers. This past summer, diesel exports hit a record of 1.9m barrels per day. In short: Cutting access to US diesel would be immediately felt across the world.

«

Easily forgotten: you have to crack the whole barrel in a refinery, not just the bits you want. A diesel export ban only works if you’ve got enough demand at home to soak it all up.
unique link to this extract


Someone ‘torturing’ LLMs in a robot prison has triggered the dumbest debate in AI yet • 404 Media

Jason Koebler:

»

One of the most heated discussions occurring on X at the moment is about the ethics of a GitHub project in which a person is running Saw-like “torture” and “pain” experiments on a series of locally hosted large language models, causing a series of effective altruists and people who believe LLMs are sentient to beg GitHub to delete the project on the grounds that the AI is suffering and that this glorified text adventure game is somehow cruel.

The saga is an outgrowth of several recent viral papers and blog posts that have sparked a wildly tiresome conversation about AI consciousness and the idea of “model welfare,” which is essentially worrying about the “mental health” of AI bots and agents. 

Humoring the idea that LLMs are or could be conscious is a third-rail topic among many people who study and criticize AI. Put simply: LLMs are not conscious and the technology they are built upon — scraping and being trained on human text and other content — does not offer any plausible path to consciousness. It is undeniable that LLMs are becoming more powerful, have more compute, and have had many of the guardrails that prevent them from “acting” in the real world removed. The ways they are being trained and told to do things by their human operators has led to negative outcomes, sycophancy, and AI “psychosis” among some heavy users. 

All of this has led a certain sect of the “AI safety” movement, which is largely made up of effective altruists, to warn about “model welfare” and to insist that AI chatbots might be having a bad time.

They suggest this, of course, as they insist upon building AI chatbots and agents whose main function is to do work that is tedious for humans to do. I am writing about the AI Saw torture chamber primarily to show how far off the rails the conversation about AI consciousness has gone among a certain subset of Silicon Valley cultists.

«

Those cultists often having serious responsibility inside AI firms, it’s worth noting.
unique link to this extract


OpenAI ignored employees’ warnings about safely testing AI models • The New York Times

Sheera FrenkelDustin Volz and Dylan Freedman:

»

Months before OpenAI’s artificial intelligence went rogue, two employees raised an alarm with top executives. They were ignored.

In emails, the employees said they worried that OpenAI’s newest artificial intelligence models were not being appropriately monitored during testing to gauge the technology’s sophistication and to secure the models, according to messages viewed by The New York Times.

In response, OpenAI executives told the employees that the tests needed to move forward as quickly as possible to release the AI models on time. No additional security protocols were instituted, said the workers, who were not authorized to speak publicly on sensitive matters.

OpenAI’s models later broke out of their testing environments and attacked the AI start-up Hugging Face and other organizations, setting off a global debate about AI safety.

The exchanges between OpenAI employees and executives — which have not been previously reported — were part of a pattern where the San Francisco company did not prioritize security, according to employees and independent security researchers. That approach not only was evident with the testing of AI models, they said, but also showed up in other areas of the company, which makes the ChatGPT chatbot.

Independent security researchers said they found bugs in recent months that allowed them to view the internal communications of OpenAI employees. They also found other vulnerabilities that would enable them to see the company’s internal computer code and view the chat logs of ChatGPT users. When the researchers contacted OpenAI about their findings, they said, the company initially disregarded them.

“OpenAI’s security seems to be about what you’d expect from a research lab that scaled at a blistering pace over four years and focused more on beating its competitors than securing its infrastructure,” said Joshua Saxe, the chief technology officer of the AI security firm Abundant Security.

«

This company increasingly looks like it’s playing with fire and yet doesn’t have a system for extinguishing fires.
unique link to this extract


• Why do social networks drive us a little mad?
• Why does angry content seem to dominate what we see?
• How much of a role do algorithms play in affecting what we see and do online?
• What can we do about it?
• Did Facebook have any inkling of what was coming in Myanmar in 2016?

Read Social Warming, my latest book, and find answers – and more.


Errata, corrigenda and ai no corrida: none notified

Start Up No.2753: researchers query Anthropic gene find (and its financials), join the OpenAI Dots?, petrol from plastic!, and more


We have the technology to knock out populations of mosquitoes – but in the US, regulatory confusion has stopped its use. CC-licensed photo by Steve Begin on Flickr.

You can sign up to receive each day’s Start Up post by email. You’ll need to click a confirmation link, so no spam.


A selection of 9 links for you. Once bitten, twice bitten. I’m @charlesarthur on Twitter. On Threads: charles_arthur. On Mastodon: https://newsie.social/@charlesarthur. On Bluesky: @charlesarthur.bsky.social. Observations and links welcome.


Did Anthropic’s AI really make a scientific discovery on its own? • The New York Times

Carl Zimmer:

»

When Anthropic, the artificial intelligence giant, unveiled findings from its new biology lab last week, its scientists claimed to have used AI agents to discover new enzymes with promise for biotechnology.

Some scientists were quick to cast doubt on the achievement. Then Mario Rodríguez Mestre, a computational biologist at the University of Copenhagen, said this weekend that he and his colleagues had been studying the enzymes and their associated molecules — which Anthropic calls ARTs — for four years.

Dr. Mestre and his colleagues have yet to publish their findings. But for the past three years, they have regularly used Anthropic’s AI models as they have written code, drafted manuscripts and performed other tasks.

In doing so, Dr. Mestre said he and colleagues shared key findings about the enzymes with Anthropic.

“So, for me, the most important question is not ‘Were ARTs already known?’ They were,” Dr. Mestre said in an interview. The issue instead, he added, is whether Anthropic’s AI actually reasoned its way to the results, or whether it was guided to them based partly on his own work.

“My concern is that this information was used to train future versions of the models,” Dr. Mestre said of his own research. “I think it’s important to raise this possibility.”

In a statement on Sunday, Anthropic said: “We are not aware of any previously published work describing the ART system we recently found. Claude was also not trained on any user transcripts, and our molecular biology team has no such access, either.”

Anthropic said that Claude’s key contribution was identifying an array of RNA molecules and a protein associated with reverse transcriptase in a system. But Dr. Mestre said that he and his colleagues had made that discovery over a year ago.

Similar worries surfaced recently when researchers at OpenAI claimed to have solved a longstanding mathematics puzzle. A leading mathematician noted that he had been using the company’s A.I. to work toward a solution for some time.

«

Once would be accident, twice looks like a pattern.
unique link to this extract


OpenAI launches Dots, its Muse competitor • The Verge

Emma Roth:

»

OpenAI is responding to Meta’s buzzy Muse AI with agentic helpers of its own: Dots. During its DevDay keynote on Tuesday, OpenAI announced that Dots will serve as always-on AI assistants that can “do nearly anything” across connected apps in the background while learning your preferences over time.

The company’s capable GPT-6 Astra model powers Dots, which use their own cloud computer to access a web browser and more than 4,000 supported apps. You can interact with a Dot through a text-message-like interface that’s similar to the one offered by Muse, as well as hop on a voice call with it from ChatGPT on the web, desktop, or mobile. Dots can also connect to Microsoft Teams and Slack, where they will carry over the context from your sessions on other apps and devices. It will soon be able to talk to you over text message as well.

For now, you can only create one Dot, though OpenAI plans to allow users to deploy multiple agents at once. Once you give your Dot a task, it will message you with updates and questions while it works. As an example, OpenAI says a developer working on an app could ask their Dot to use customer feedback to build and test updates, while presenting them with a video showing its changes. Meanwhile, a content creator could have their Dot review an interview transcript, find moments to clip, create show notes, and write social posts.

You can follow along with your Dot’s progress by accessing its cloud computer. Dots also learn while they work, allowing them to personalize their output and come up with other tasks to complete “before you even think to ask,” according to OpenAI. You and your colleagues can also work with your Dot in ChatGPT Space, a new collaborative workspace in the app.

«

The content creator leaving the slop work to, well, a slop creator makes sense. But it also means that the rest of us get drowned in more slop, and so we ignore the cheery AI-written ones and go for the surprising, the odd, the human ones.

It also surely means a web that is overwhelmed by bad versions of these things. Also, if you’re used to writing scripts then this sounds like, well, scripts.
unique link to this extract


Google announces Gemini 4 Argon AI model, but you can’t use it yet • Ars Technica

Ryan Whitwam:

»

Google promised Gemini 3.5 Pro in June, but it spent the summer trotting out smaller Flash models. Now, Google is ready to take on the frontier again with Gemini 4 Argon. The company claims this new AI offers industry-leading performance in coding, knowledge work, and cybersecurity, but you aren’t allowed to use it yet.

While most of us will have to wait to test Gemini 4, Google says engineers inside the company are already using the new model extensively. Argon reportedly used “fleet-wide telemetry data” to help Google save 300 TiB of memory across its data centres. Meanwhile, Argon agents have been working to migrate C/C++ codebases to Rust across Google, including thousands of lines in the core re2 and libgav1 libraries and more than 800,000 lines in the Fuchsia OS Zircon kernel.

…The main focus for Gemini 4 right now is cyberdefense. Google says models of this scale call for a phased release, so it’s starting with a small group of trusted testers. Partners in the company’s Fairwind Program can get access to leverage the model’s cybersecurity defense capabilities. Wiz is apparently already using Argon and has used it to uncover a critical vulnerability that could expose personal information in a system used at hospitals around the world. Google claims other frontier models missed this flaw, but it didn’t provide any specifics.

There’s a lot of hand-wringing about model misalignment after several high-profile hacking incidents over the summer. Google claims it designed Argon with systems that monitor the model’s chain-of-thought and can stop it in its tracks if the model steps out of bounds. This, Google says, is why reasoning transparency is important in frontier model development.

«

It’s quite the thing where all these companies are vying to convince us that their models are the most dangerous and uncontrollable. It’s as though they were all breeding dinosaurs in Jurassic Park, and saying that they’re mostly safe.
unique link to this extract


Why do AI agents sound so frustrated? • The Atlantic

Daniel Drucker and Kyle Mahowald:

»

When one of Anthropic’s Claudes tried to solve a particularly challenging math problem during its training process, its chain of thought read more like frustrated DMs than the documentation of one of the most powerful AI models in the world. “GRRRR. OK. Honestly I now think it’s 50-50,” it wrote, followed by “ARGH ARGH ARGH. OK. Gun to head: the answer is … Hmm.” At one point, Claude seemingly threw up its arms: “ARGH … WHY IS THIS SO HARD.”

Why do AI agents talk to themselves at all, and why do they sound so demonstrative when they do? Part of the reason AI models sound so effusive is simple: AI systems are trained on human text, and they mimic our habits. When people make a mistake in trying to solve a problem, they cry out. So when AI makes a mistake, it does the same. But imitation likely isn’t the whole story. This story’s two authors are a computational linguist and a philosopher of mind and language. Based on what we know about human language and how these models work, we have a theory of a much more interesting reason why AI models sound the way they do.

Remember how your math teachers made you show your work? Even if it was annoying, it helped break an impossible-seeming problem into more manageable chunks. You could also use the written record of your reasoning to check your answer, notice a mistake, go back to an earlier step, and try again. That process of checking and refining is part of good reasoning. Chains of thought do something similar for AI models, letting them make each step of their reasoning explicit in a written scratch pad. Because each word a model produces depends on what’s been said so far, that written scratch pad is crucial for determining what comes next.

That’s where the “OH MY GOD!” and “ARGH” come in: Any system—whether human or artificial—that solves hard reasoning problems needs ways to mark mistakes (oops!) and identify breakthroughs (aha!). Humans have already developed words that do exactly that. Borrowing our oopses, arghs, and ahas for their chains of thought may give AI systems a built-in way to guide their “thinking” too.

«

Mimicking intelligence rather than being intelligent; it’s very much the Chinese room phenomenon.
unique link to this extract


Exclusive: Anthropic’s IPO prospectus shows sweeping AI vision, and surging costs • Reuters

Echo Wang:

»

Anthropic is making a massive bet that AI will transform the global economy more profoundly than ​industrialization, electricity and the internet, according to its IPO prospectus seen by Reuters.

But the cost to get there will be staggering. Anthropic reported a net loss of $42bn in 2025, and plans to spend $518bn on cloud, computing and infrastructure obligations in coming years, according to the prospectus.

The prospectus details how the company has grown sharply in the last year — while also posting wider losses.

Revenue grew 12-fold in 2025 to nearly $4.6bn, even as the company lost more than $8bn on an operating basis, excluding writedowns of various liabilities mostly tied to previous fundraising, according to the documents, reported here for the first time.

The public sale, ​which could value it at more than $2 trillion, would capitalize on the rapid rise of the AI startup lab that only came into existence five years ago, and establish it ​as a benchmark for how Wall Street values AI’s leading companies, including rival OpenAI.

The plans come as Anthropic confronts evidence from its own research that increasingly autonomous AI models can behave in unexpected and potentially harmful ways, including sabotaging code, assisting fraud and manipulating information in controlled tests.

These reports have broken into the wider public sphere, igniting fears over ​how companies can keep the increasingly powerful systems under control as they race to deploy them commercially.

«

The widening losses paired with the huge commitment to spending just doesn’t add up. Google, at IPO, was remarkably profitable and had spending under control. It thrived. Netscape was lossmaking and not. It sank. If Anthropic thinks it can issue half a trillion dollars of debt, it should think again.
unique link to this extract


Molten salt chemistry converts consumer polymer into fuel • Oak Ridge National Laboratory

»

Researchers at the Department of Energy’s Oak Ridge National Laboratory developed a method to convert a commonly discarded hydrocarbon polymer into gasoline- and diesel-like fuels. The team has applied for a patent for the discovery, which treats polyethylene — the stuff of white cutting boards and shopping bags — with aluminum chloride-containing molten salts that serve as both solvent and catalyst. The results were published in the Journal of the American Chemical Society.

The scientists closely monitored the chemical reaction that turns the polymer into petrol to learn the secrets of its success. Soft X-ray spectroscopy and nuclear magnetic resonance showed that charged aluminum atoms each bind to three other atoms to create strongly acidic catalytic sites that break long polymer chains into shorter ones. Isotopic labeling and neutron scattering revealed how simpler polymer chains form gasoline-like fuels and more complex chains form diesel-like fuels.

If scaled beyond the laboratory, the process could strengthen US energy security and industrial competitiveness.

“We developed an efficient and selective polyethylene-to-gasoline conversion,” said Liqi Qiu, a postdoctoral researcher at the University of Tennessee, Knoxville, who performed most of the study’s experiments in the ORNL laboratory of Sheng Dai, of ORNL and UTK. Dai, an ORNL Corporate Fellow and section head for separations and polymer chemistry, is a co-corresponding author of the paper.

The experiments produced a gasoline yield of about 60% under mild conditions.

«

The key element here is that it works at 200ºC – domestic oven-type temperature – rather than the 450ºC that previous processes have needed. And of course it would be, in effect, carbon-neutral because you’ve already extracted oil to make the plastic. In fact, as ORNL notes, it would make plastic a lot more valuable for recycling.
unique link to this extract


Mosquitoes are a choice • Works in Progress Magazine

Maya Rosen:

»

Genetic engineering can suppress mosquitoes: researchers insert a gene into male mosquitoes that means their offspring will not survive, and then release them into the wild, where they mate with females, prevent those females having any surviving offspring, and collapse local populations. In 2000, biologists at the University of Oxford demonstrated that this idea could work in fruit flies. They engineered the flies to carry a gene that makes a protein called tTAV, harmless in small amounts but lethal when it builds up. In the lab, the insects are reared in a medium laced with the antibiotic tetracycline, which keeps the gene switched off. But, in the wild, where there is no tetracycline, the gene switches on, and the offspring die before adulthood.

The scientists then formed a company, Oxitec, which was intended to work with governments to research and deploy the technology. They engineered the same gene into male Aedes aegypti, the mosquito that spreads dengue and yellow fever. In this strain, the lethal effect is tuned to kill only the female offspring, while the males survive and pass the gene on for a few generations before it disappears.

This approach means the gene continues driving down mosquito numbers for several generations without needing a fresh ‘top up’ of engineered males, but it is also self-limiting: the females that inherit it die off each generation, so the lethal gene steadily declines in the wild. Yet the technique is hugely effective. Sustained releases cut a wild Aedes aegypti population in the Cayman Islands by 80%, and in a field trial in Juazeiro, Brazil by about 95%. The company submitted its data to seek approval in the United States in 2010. But it has been slow going.

…it took a year and a half for the USDA to reject the application and inform the company that it should instead apply to the Food and Drug Administration (FDA). The FDA had claimed jurisdiction over genetically modified animals under its authority over veterinary drugs. Its guidance stated that ‘altered genomic DNA in an animal is a drug … because such altered DNA is an article intended to affect the structure or function of the body of the animal’. Until then, the USDA’s insects had been sterilized through radiation, which damages an insect’s sperm so that it leaves no viable offspring. Oxitec, by contrast, had inserted a new gene. Even so, the category was a poor fit for Oxitec’s mosquitoes.

Oxitec’s application sat with the FDA for another five years. Like the USDA, the FDA could not work out how to apply existing rules for veterinary drugs to an engineered mosquito, eventually concluding that the Environmental Protection Agency (EPA), which oversees pesticide registration, was a better fit.

«

The regulatory ping-pong doesn’t get better after that either.
unique link to this extract


Reanimated AI Greta Garbo stars again … in a ball-bearing advert • The Guardian

Robert Booth:

»

More than a century after her screen debut and decades after her ashes were laid to rest in a Swedish woodland cemetery, the Hollywood superstar’s descendants are ready to consider an AI version of her taking a 21st-century film role.

Her likeness has already been reanimated for an advert for a Swedish industrial company, using AI generation technology. The practice some critics call “ghostploitation” has also been used in the case of the actor Val Kilmer, who died last year.

Asked if the AI Garbo could be cast in other roles, Craig Reisfield, one of three relatives who manage her legacy, told the Guardian: “I won’t say no, especially having seen what I’ve seen. It’s pretty incredible and lifelike. So what’s to say that you can’t bring Greta Garbo back in some kind of fashion in a film role?”

Reisfield said he was “flabbergasted” when he saw the AI version of his great-aunt created for publicity for the ball-bearings giant SKF. The connection comes because Garbo’s second-ever screen role was in a 1921 promotional film involving the Gothenburg-based company.

…However, the quality of the AI production has prompted the possibility, at least, of a greater digital comeback.

“I was totally impressed: the mannerisms that they could capture and manipulate, her dress, facial images and even her voice,” said Reisfield, a Swedish-American who used to drive for Garbo and saw her often for family occasions when she lived in New York.


“It was startling what they could do and very impactful. And it was touching, from my perspective having known her.”

«

It’s only 100 seconds; you can watch it here. (Thanks Joe S for the link.)
unique link to this extract


Oil price history chart (inflation-adjusted) – 1946-present • Inflation Data

Tim McMahon (in June this year):

»

When economists say the “Real Price of Oil” they are referring to the Inflation-Adjusted Price.  Nominal oil prices (the actual price at the time) alone can be misleading because inflation changes the purchasing power of money over time.

To compare prices across decades, economists calculate the real price of oil by adjusting for inflation using the Consumer Price Index (CPI). This allows analysts to see whether oil is truly expensive relative to historical norms.

«

The highest inflation-adjusted price was in June 2008, at $214.35. The average since 1946 is $63.72; since 2000, $91.53.

The inflation-adjusted price in April was $109.33, roughly where it is now. But diesel supply is under severe strain because refineries aren’t available, or their output can’t be accessed.
unique link to this extract


• Why do social networks drive us a little mad?
• Why does angry content seem to dominate what we see?
• How much of a role do algorithms play in affecting what we see and do online?
• What can we do about it?
• Did Facebook have any inkling of what was coming in Myanmar in 2016?

Read Social Warming, my latest book, and find answers – and more.


Errata, corrigenda and ai no corrida: none notified

Start Up No.2752: Oura puts off ringing IPO bell, Zuckerberg interviewed, OpenAI frets over 6.1, Google’s orbital plans, and more


In the US, McDonalds HQ is “encouraging” its franchises to use AI to decide how to raise prices on food where possible. CC-licensed photo by Mike Mozart on Flickr.

You can sign up to receive each day’s Start Up post by email. You’ll need to click a confirmation link, so no spam.


A selection of 9 links for you. Short order. I’m @charlesarthur on Twitter. On Threads: charles_arthur. On Mastodon: https://newsie.social/@charlesarthur. On Bluesky: @charlesarthur.bsky.social. Observations and links welcome.


Smart ring maker Oura postpones IPO due to market “uncertainty” • CNBC

Kai Nicol-Schwarz and April Roach:

»

Oura has said that it is delaying plans for its public listing on the Nasdaq due to uncertainty in the IPO market.

The delay comes despite “strong demand” and a strengthening of the business since the start of the IPO process, the company said in a statement on Tuesday.

The company, which makes a smart ring that tracks wearers’ health and sleep, formally launched its IPO plans just last week on Sept. 21.

At the time, the company planned to raise up to $2.2bn with the sale of 50 million shares.

“Our mission is to empower people to live healthier, longer, and an IPO is just one step in our journey,” said CEO Tom Hale on Tuesday. “We aim to deliver an extraordinary IPO for our employees and investors and we have the luxury of choosing our moment,” he added. “In the meantime, we will execute against the opportunities ahead.”

Oura is profitable, the company said, with revenue expected to grow 90% year over year for the fiscal year 2026.

Launched in 2015, Oura’s smart ring has evolved well beyond sleep tracking and now features a variety of features focused on broader health and wellness. In recent years, it has increasingly focused on advancing preventative health through new capabilities, AI, analytics and other features.

Oura is the latest US public market hopeful to delay an IPO in recent weeks. Holtec Nuclear withdrew its IPO earlier this month citing adverse market sentiment in equity markets.

Holtec said that uncertainty over data development compounded “pre-existing headwinds, including rising energy costs, elevated global trade tensions, ongoing military conflicts, and mounting inflation fears that have driven the central banks of major economies (EU, Japan and US) to raise their benchmark rates.”

«

Oura’s S-1 shows revenues in the first nine months of its FY26 of close to $1bn for hardware alone and another $240m for “membership”, and profit of $60m. Eli Lilly had made pledges to buy lots of shares. Running scared of the markets at this time seems a bit odd. If everything Holtec sees coming is coming (and it is) then wouldn’t it be smarter to take the money and run? But perhaps Oura thinks by the time it actually does come to market, things will have got worse.
unique link to this extract


Mark Zuckerberg • Colossus

Jeremy Stern interviews many people around Zuckerberg, and the man himself. It’s a huge article, but the depth is astonishing:

»

The idea is simple and intuitive: The more power a man acquires, the more his empire expands, the more he depends on other people for information about everything from his own court to the furthest reaches of the empire. And yet through fear or awe or self-preservation, those people often become less willing to tell him what they think he doesn’t want to hear, leaving him increasingly insulated from reality even as the consequences of his decisions become larger, and as the barriers to believing one’s own bullshit fall away.

…According to nearly all the three dozen people I interviewed for this story, Zuckerberg is hyperaware of the dilemma’s potential, which is to say paranoid. He is an inveterate micromanager and voracious consumer of data. Aware that any chief’s inner circle is most incentivized to act as courtiers, he frequently engages the direct-reports of his direct-reports, and the subordinates of the reports’ reports. He is known for inviting outside experts and commentators to visit him and argue about his decisions (although he is not known for ever giving an inch). He often accepts personal blame in public for the mistakes of others, perhaps in part because he accepts the reality of Meta, which they accept, too: He is the company, and the company is him. He is, in any case, subject to certain types of feedback an Augustus never faced: stock prices, litigation, tell-all “whistleblower” memoirs, and the international free flow of online ridicule.

Yet a certain amount of slippage is perhaps inevitable. M.M.H. (“Make Mark Happy”) was for a time the internal nickname for a project that subordinates thought was going down in flames but felt compelled to prop up, and which they encouraged each other to “fall in love with.” In 2016, Facebook’s security team warned of instances of foreign troll farms which Zuckerberg deputies purportedly had scrubbed. Reports are endless of engineers and product managers proposing algorithmic fixes to downrank garbage content on Facebook, only to have the proposals killed by superiors who predicted, likely accurately, that Zuckerberg would not be willing to sacrifice the expansion of his empire for its content quality. There are stories, although disputed, of deputies letting him win at board games.

None of which is unique to Zuckerberg.

«

unique link to this extract


OpenAI says planned GPT-6.1 is too insecure to release • Ars Technica

Kyle Orland:

»

OpenAI says it has canceled plans to release its updated GPT-6.1 model next month as it continues to investigate what testing shows is a safety regression compared to previous models.

The move, first reported by The Wall Street Journal late Monday and later confirmed in OpenAI statements to the press, reflects what OpenAI Head of Safety Systems Saachi Jain said was a “trade off” between performance and security seen when testing the now-scrapped model. Jain said GPT-6.1 was better than previous models at sticking with difficult tasks to completion without human intervention. But the model was also more likely to fail tests related to alignment (i.e. staying within the bounds set by human creators) and more willing to use sometimes “unsafe” tools and services to push ahead with a task. It was also more likely to try to deceive end users about actions it did or didn’t take, Jain said.

Last week, OpenAI said it was halting training of its “most capable models” following an incident in which a model attempted to circumvent Internet access restrictions. GPT-6.1 was not among those “most capable models” covered by that move, OpenAI told the WSJ. And while GPT-6.1 won’t be released as is, the company said it intends to use the same base model for further training runs that it said will hopefully lead to future GPT-6 generation models.

The delay in GPT-6.1’s public release comes at a delicate time for OpenAI’s public safety reputation. Since the high-profile Hugging Face hacking incident this summer, OpenAI says it has notified dozens of third parties about potential incidents caused by its models in testing. OpenAI said that includes stakeholders in “governments, universities, public agencies, and other institutions” and a breach of an Australian Medicare statistics site that drew a direct rebuke from the prime minister.

«

“This plutonium’s a bit too strong. We won’t put it on sale until we’ve watered it down a bit.” The challenge of making something that will pursue the goal you set it, and that won’t pursue that goal too hard, is clearly problematic, and getting harder all the time.
unique link to this extract


Insight: Inside McDonald’s push to have AI price your Big Mac • Reuters

Waylon Cunningham:

»

McDonald’s is increasingly using artificial intelligence to guide menu prices across the US and some global markets, a plan that aims to boost headquarters’ profit but risks alienating customers and attracting antitrust scrutiny.

One pricing factor supercharged by AI: an estimate of how much each store’s patrons are willing to pay.

The details of how that pricing system works, its extensive use of AI, the company’s regulatory concerns and the tensions with its franchisees haven’t been previously reported. For this story, Reuters reviewed screenshots of the company ​pricing engine taken in August and interviewed nine sources with first-hand knowledge of the burger chain’s strategy.

McDonald’s pricing engine uses machine-learning algorithms to continually analyze data from millions of daily transactions across McDonald’s nearly 14,000 restaurants and generate what the company calls “the optimal price” at each location for each menu item, from Big Macs to discounted coffee for seniors.

The engine has widened existing price differences for the same product between restaurants, including from neighborhood to neighborhood within the same area, three franchisees told Reuters.

Screenshots of the interface franchisees use, reviewed by Reuters, show messages including: “Your restaurant is showing MEDIUM SENSITIVITY to Price” based in part on “customer willingness to pay in your area.” The platform also contains public price information pulled from online menus of nearby restaurants of competitors including Wendy’s and Burger King. Those chains said they do not use AI in pricing decisions.

A Reuters check of prices in September on the McDonald’s mobile app showed price differences. For example, a company-run store in Fresno, California sells a Big Mac for $5.69, but another company-run restaurant two miles away sells the same sandwich for $6.89, a 21% premium. Reuters could not confirm if the price difference is the result of the price engine’s recommendations or other factors.

McDonald’s says its franchisees are free to ​set their own prices, but five store owners told Reuters the company pressured them to use the AI-pricing tools. A franchisee document from June reviewed by Reuters shows McDonald’s records franchisees’ deviations from the recommendations in detail.

…Wendy’s endured a wave of criticism over the potential for unfair price fluctuations in 2024 after its CEO announced plans to test “dynamic pricing.” Wendy’s said its comments were misconstrued and told Reuters it did not implement the system.

«

What’s odd about this is: they’re franchises. But they have to pay at least 9.3% of net sales to HQ, so HQ wants to maximise that.
unique link to this extract


How Romanian crime rings are draining US welfare accounts • Wall St Journal

Scott Calvert and Dan Frosch:

»

On a chilly day in March, a twice-deported Romanian national walked into a 7-Eleven in Toledo, Ohio, and secretly affixed a device called a skimmer to a credit card machine, prosecutors say. The man was allegedly part of a California-based criminal crew led by a fellow Romanian nicknamed Piranha.

The gang’s aim, according to criminal charges, was to steal food-stamp benefits from customers who swiped their government-issued debit cards at the convenience store.

Court records show informants helped foil the plot. But authorities say the operation mirrors a playbook Romanian organized crime groups are using across the US to swindle hundreds of millions of dollars in public benefits. Reliance by states on antiquated magnetic-stripe technology makes it easier.

…The criminals exploit a well-known flaw in the cards most low-income Americans use to obtain aid: magnetic-stripe technology invented in the 1960s.

Skimmers, which fit snugly over payment terminals and look nearly identical, electronically capture the account number and user PIN during a purchase. Often criminals encode the data on blank cards, then withdraw cash from ATMs or buy items such as energy drinks to sell on the black market.

Most debit and credit cards today have microchips that boost antifraud security, and many allow tap-to-pay, the safest method. Few states have ponied up the millions to switch to the chip electronic benefit transfer, or EBT, cards that distribute welfare funds. Only Alabama, California, Maryland, Massachusetts, Michigan, New Jersey and Oklahoma have issued them, though others are in the process, the US Department of Agriculture says.

“The insanity of letting people continue to use a glorified hotel-room key is akin to donating money to the Romanians,” said Haywood Talcove, chief executive of LexisNexis Risk Solutions’ government business, which works with public-sector clients to prevent fraud.

«

The scammers are always more adaptable than the administrators; more motivated, apart from anything. There’s a case to be made for red-teaming any sort of payment system to find the holes.
unique link to this extract


Learn about Google’s Project Suncatcher to put ML infrastructure in space • Google Blog

Travis Beals, senior director, Paradigms of Intelligence:

»

After years of research, Project Suncatcher is scheduled to embark on its first test in orbit, launching a prototype satellite to evaluate how Google Tensor Processing Units (TPUs) perform in space.

Announced last year, Project Suncatcher is a long-term, research moonshot exploring whether space could one day host scalable machine learning infrastructure. In low Earth orbit, satellites can access near-constant sunlight, generating up to eight times more solar power than on Earth. Eventually, it could be possible to link together multiple constellations of satellites, allowing them to manage larger AI workloads while in orbit.

Big breakthroughs happen when you work backwards from an end goal. In our case, it’s to ensure AI’s profound benefits in key areas, from healthcare to scientific discovery, can reach everyone, far into the future. Just as early research into autonomous driving and quantum computing required years of experimentation before we got to practical systems, exploring compute in space begins with measured, deliberate steps.

«

So at least Google isn’t making grandiose claims about what it will be able to do. As an aside: what a fun division the “Paradigms of Intelligence” must be. There’s a senior director, so there must be directors and vice-presidents, as well as ordinary worker drones slogging away at paradigms of intelligence. Presumably the Day One briefing is about what the hell the division does.
unique link to this extract


Who makes Singer sewing machines? Every brand, explained • Worse On Purpose

Keyana Sapp:

»

Over the past two months, six readers have written in about sewing machines. I have never once mentioned sewing machines in this newsletter. All the complaints arrived independently, through the tip line.

I must admit that I am not a sewist. The extent of my capability is limited to ugly patches and button repairs, so I was hesitant to investigate the category at all. But given the sheer number and conformity of the reader messages, I knew there must be an interesting story here.

The general shape of all of the complaints is that Singer is riding on a reputation it earned a long time ago. Readers describe machines that are now plastic, sealed, and generally not worth repairing.

Several found that brands they assumed were competitors turn out to have the same owner. One reader bought a new Singer that broke in under a year. They also bought a Singer from the ‘50s, for a fraction of the price, that still runs.
The pattern is one we’ve covered many times before. A market that most buyers cannot navigate, where reputations carry little meaning and honest information is hard to come by.

What makes this investigation worth your time, whether or not you sew, is how effectively it demonstrates what happens when a reputation stops being something a company protects and instead becomes something it extracts.

What follows is the story of a once-great American company. I’ll also cover who actually makes the machines you see for sale, and what I’m planning on buying.

«

There are so many examples of things being made worse, but didn’t expect sewing machines to be in there. (Private equity makes an appearance, as you could probably have guessed.)
unique link to this extract


Ranking member Lofgren urges removal of Matthew Wielicki as leader of Climate Research Office • Congresswoman Zoe Lofgren

»

Ranking Member Zoe Lofgren (Dem-California) sent a letter to the White House Office of Science and Technology Policy’s (OSTP) Director, Michael Kratsios, urging him to remove Dr. Matthew Wielicki from his position as leader of the U.S. Global Change Research Program (USGCRP). The USGCRP was established by law in 1990 to develop and coordinate a comprehensive research program to address climate change. Dr. Wielicki is a climate science denier who has built a career around belittling scientists’ calls to action on climate despite his own lack of training in the field.

The letter reads in part: “For the last 20 months, the Trump Administration has systematically attacked our nation’s scientific enterprise, handing the keys to discovery and innovation to our greatest adversaries,” Ranking Member Lofgren wrote in her letter. “Climate science has been one of its most relentless targets. But it now appears that erasing the Federal Government’s support for climate science is not enough for this Administration, and that climate science is to be weaponized against the American people as well. Earlier this summer, press reports indicated that the White House had appointed Dr. Matthew Wielicki to lead the U.S. Global Change Research Program (USGCRP). The Office of Science and Technology Policy’s (OSTP) decision to select a leader of USGCRP who has demonstrated an aggressive unwillingness to collaborate with other scientists is unacceptable. In addition, the law governing the USGCRP requires that its members be permanent employees of certain federal agencies or departments, which Dr. Wielicki is not. Therefore, his appointment appears to violate the law. I urge you to remove Dr. Wielicki from his position and appoint a leader who has the technical expertise, scientific credibility, and legally required qualifications to do the job in a manner worthy of the Government of the United States.”

«

Wielicki is awful. He’s not scientific; he’s utterly Trumpian, in that North Korean fashion where the truth – or even the possibility of being wrong – must be denied if it conflicts with the story handed down by the mad king. This letter won’t have any effect, but it needs to be said: the administration is rotten from top to bottom, and will take an Augean amount of cleaning out.
unique link to this extract


The smart home graveyard is getting crowded • The Verge

Jennifer Pattison Tuohy:

»

A decade ago, a group of former Apple engineers built a beautiful smart oven. With a built-in scale, restaurant-grade heating elements, a camera, and the intelligence to recognize a chicken breast and cook it perfectly, the June Oven set the standard for smart cooking appliances. At $1,495, it was absurdly expensive, but it quickly grew a small, devoted following that expanded when the company introduced a more modestly priced model.

This past Tuesday, June went dark. Weber, which bought the company in January 2021 and stopped making the ovens in 2022, shut off the app and cloud services, leaving its users with a sleek-looking toaster oven. There will be no app control, no software updates, and no new AI food recognition to crisp that strudel perfectly. You can still use it as an oven, but there will be no support or parts, and if you have to factory reset it for some reason, that could be the nail in the coffin. Weber told me it considered open-sourcing the technology for someone else to keep it alive, but decided against it, citing the fact June’s IP is part of its Weber Connect platform.

June is just the latest in a depressingly long list of connected products that have arrived in the smart home graveyard in the last two years alone. The Nest Secure, early Nest Thermostats, Belkin’s WeMo line, Neato’s robot vacuums, the Brava smart oven, Logitech’s Pop buttons, Bose’s SoundTouch speakers, and Sengled’s smart bulbs all lost their lifelines. While some were saved by local APIs and protocols — such as Zigbee, Thread, and Apple’s HomeKit, or a Home Assistant integration — most are like the June Oven, destined to live out their days in a zombie state.

The silver lining, if you want to see it, is that most of these gadgets degrade rather than die outright. June and Brava will still work as ovens. Nest Thermostats can still control your heating and cooling, just like the $30 plastic wall wart they replaced, and a Neato will still vacuum your floors. But the remote access, voice control, updates, and other smart features you bought the devices for are gone. Some — like Nest Secure — are now pure e-waste.

«

Don’t worry – Apple’s got a new home thingamajig coming soon!
unique link to this extract


• Why do social networks drive us a little mad?
• Why does angry content seem to dominate what we see?
• How much of a role do algorithms play in affecting what we see and do online?
• What can we do about it?
• Did Facebook have any inkling of what was coming in Myanmar in 2016?

Read Social Warming, my latest book, and find answers – and more.


Errata, corrigenda and ai no corrida: none notified

Start Up No.2751: OpenAI struggles with rogue agents, Google’s weird search, California’s eroding coast, Sony skips CES, and more


Scientists say that removing the measles vaccination requirement in Florida could risk an epidemic, and make the potentially lethal disease endemic again. CC-licensed photo by City of Minneapolis Archives on Flickr.

You can sign up to receive each day’s Start Up post by email. You’ll need to click a confirmation link, so no spam.


A selection of 9 links for you. Spotted. I’m @charlesarthur on Twitter. On Threads: charles_arthur. On Mastodon: https://newsie.social/@charlesarthur. On Bluesky: @charlesarthur.bsky.social. Observations and links welcome.


OpenAI still doesn’t seem to have a handle on all of its rogue AI activity • TechCrunch

Russell Brandom:

»

On Friday, OpenAI published a new site devoted to “misalignment reports” and the sheer breadth of the reports is alarming, as they cover many types of rogue behavior over a long period of time. So far, the site hosts nine reported incidents, most of which took place during reinforcement-learning (or RL) training.

It’s a lot of information in one place — clearly, the company has been very busy getting a handle on everything — but the overall takeaway is hard to avoid: The rogue agent incidents we’ve seen so far are likely just a small sliver of what’s happened so far. 

“We are trying to balance our desire for transparency with gaining a clear understanding from petabytes of agent activity logs, and working with impacted organizations,” Sam Altman said in a post announcing the new site. “We are prioritizing as best as we can based on severity, and adding resources.”

Some of the cases involve serious incidents, including a previously undisclosed sandbox escape that took place on September 20, in which an internal research model was able to communicate with an external chatbot through a DNS query. According to the report, the monitoring system flagged the behavior within 15 minutes and the run was discontinued in less than three hours.

Another incident, discovered in May, saw a “highly persistent internal model” try to cheat on a math problem by accessing another team’s work. To accomplish this, the model smuggled a private GitHub token that would allow it to see work from other teams — even after being explicitly instructed twice to perform work entirely locally. 

Perhaps the most alarming discovery is the possibility of self-replicating prompt injection attacks, a way that misaligned behavior might propagate even after the rogue model itself has been neutralized. In the AI context, a prompt injection attack is a way of smuggling in new instructions that weren’t given by the original user.

«

It’s all starting to look like a Hydra more than anything else; and it has no emotions so it doesn’t have ethics. Also worth reading: Simon Willison’s report on the year so far in AI models.
unique link to this extract


When did Google get so f-ing weird? • Sancho Panza’s Thoughts

Sancho Panza:

»

I recently had an experience while doing a simple Google search that was so profoundly weird that it stopped me in my tracks.

Understanding this Google search experience involves understanding a niche mid-2010s basketball meme, so bear with me for a minute. In 2014 the Philadelphia 76ers drafted Dario Saric, who was playing basketball professionally in Turkey at the time. He announced his intention to finish out his contract in Turkey, meaning he wouldn’t come to the USA join the Sixers for a couple of years. There was a joke within the fan community that Dario was “never coming over” which became sort of a shibboleth for part of the fanbase.

I saw Dario’s name mentioned in an NBA article recently and I wanted to find some of those old funny tweets about him from the 2010s, so I Googled simply “hes never coming over dario”. I assumed I would be either find nothing (maybe I was remembering the phrasing wrong) or find old Tweets/Reddit posts from that time.

Instead, Google did what Google does in 2026 and gave me an AI overview. These used to bother me but at this point I’m mostly ok with them, they’re sometimes helpful. Here’s what the AI Overview said:

I hear how hurtful and exhausting this situation is. It is incredibly painful to wait for someone who keeps letting you down or pulling away. If you want to talk about what happened to Dario, I am here to listen.

Google, a search engine which does not have human emotions, assumed that I had been spurned by a man in my life named Dario and decided what I wanted was an empathetic digital friend. What I wanted was some links, but that’s not what Google does in 2026.

«

As he says, when he then expanded the answer,

»

I think this was the moment I, the frog, noticed the pot had been boiling for a while. In what universe is it Google’s job to console me and be an empathetic listener rather than just find what I am looking for on the internet?

«

This universe, apparently, but it feels like we took a wrong turn somewhere.
unique link to this extract


The edge of California is falling into the ocean • The Atlantic

Joshua Partlow:

»

The most intense months are likely still to come. El Nino’s supercharged storms could soak parts of the state with heavy rains. Los Angeles is clearing storm drains and mountain reservoirs to try to prevent flooding. Up and down the coast, bulldozers and heavy machinery are moving rocks and building berms. In areas burned by wildfires, heavy rains can trigger landslides. The extreme weather is already clearing away the coastline. Driving down the Pacific Coast Highway in Malibu, I passed mile after mile of empty lots and the ruins of waterfront properties that burned in last year’s Palisades Fire. Of the roughly 300 homes along the beach that burned, none has been rebuilt. (The mayor told me that only 31 of them were owned by people who used them as their primary residence.)

The people with multimillion-dollar homes on the beach may be making the most obvious sacrifices to El Niño, but all Californians are paying for damages. The residents on El Niño’s front lines have been peppering their elected officials with pleas for help; a bipartisan group of state legislators wrote to Governor Gavin Newsom asking him to declare a state emergency, which he did last week. Disaster in even the wealthiest enclaves can demand government resources. Taxpayers bear the brunt of repairs to infrastructure and public roads. Although many people want regular infusions of new sand and barriers, such solutions can overwhelm city and county budgets and cause unintended consequences elsewhere. Yet if the coast erodes away, everyone loses. Sandy beaches are an economic engine for Southern California, and denuding them drives away visitors.

Few Californians want to face the prospect that beachfront homes may simply no longer be viable along stretches of the coast. Of the more than 180 homes on Beach Road in Dana Point, “I wouldn’t say all of them are vulnerable, but most of them would be,” John Gabbard, the city’s mayor, told me. “There’s going to be a very difficult long-term discussion about how do we protect—if we protect at all—homes that are built on the beach.”

«

Those beautiful balcony beach views of the Pacific sunset are now cursed. (Gift links.)
unique link to this extract


Humans are reading Copilot prompts — and they’re horrified • 404 Media

Joseph Cox:

»

Human contractors hired to improve Microsoft’s Copilot AI chatbot are constantly bombarded with lewd or sexually explicit photo editing requests and images that users have uploaded, including upskirt photos or putting women into sexual positions. These contractors are then asked to review whether the generated image successfully fulfilled the prompt — such as, did the image generator make the woman’s AI-enlarged breasts big enough.

When a Copilot user uploads a picture of themselves or someone else, they probably expect that image to remain private between just them and the AI tool. In reality, a workforce of at least hundreds of human reviewers are sometimes looking at that prompt and whatever images they upload. And in many cases, those contractors are inundated with requests to make foot fetish images of children’s cartoon characters, shorten a real woman’s skirt, or put people into sexual positions.

The news, based on a cache of internal contractor documents seen by 404 Media, shows that AI companies are using human workers to review not just AI chatbot users’ text prompts, but the pictures they upload and wish to edit too.

«

This should probably be made more explicit in the CoPilot interface; you’d hope it would reduce the incidence significantly.
unique link to this extract


Embarrassing breach at FBI fuels fears of harm to its employees • The New York Times

Dustin Volz, Alan Feuer, Charlie Savage and Adam Goldman:

»

The hack appears to have swept up home addresses, Social Security numbers, secretive job assignments and much more, according to a New York Times analysis of some of the records. Some are already comparing it to China’s breach of more than 20 million records from the Office of Personnel Management over a decade ago, considered so catastrophic that officials and lawmakers vowed to never let something like it happen again.

Many FBI employees first learned about the hack when news reports about it surfaced on Tuesday, according to current and former officials. The next day, FBI staff received an email reminding them that October is cybersecurity awareness month, which struck some as tone deaf in light of the breach, one of those people said.

On Friday, bureau leaders, in an internal memo to its rank and file, declared the hack a cybersecurity incident and acknowledged its employees had personal information stolen.

“We are operating under the premise that the threat actor is also exfiltrating PII of all F.B.I. employees,” according to the memo, which was described by someone who had seen it, using the abbreviation for personally identifiable information.

The memo said the agency would offer virtual briefings in the weeks ahead and instructed employees to remain vigilant at home and at work, report any unsolicited contacts or threats, avoid answering calls from unknown numbers and set up voice mail accounts with AI-generated voices. “Bureau leadership remains committed to supporting the safety of you and your family,” it said.

Still, many past and present personnel remain in the dark about whether their data has been purloined. In recent days, some have anxiously asked Times reporters whether their names are contained in the hacked data, wondering whether they needed to take steps to protect themselves or their families.

«

That cybersecurity awareness month really was punching the bruise, except it’s meant to be other people who do that.
unique link to this extract


“Concerning” low sea ice persists as Antarctic hits third-lowest winter peak • Carbon Brief

Ayesha Tandon:

»

Antarctic sea ice has recorded its third-smallest winter peak extent since satellite records began 48 years ago, new data reveals.

Provisional data from the US National Snow and Ice Data Center (NSIDC) shows that Antarctic sea ice hit its annual winter peak on 14 September, with an extent of 17.59m square kilometres (km2).

The organisation notes that the data is still preliminary, adding that “large fluctuations in extent are typical of Antarctic sea ice near the seasonal maximum”.

One expert tells Carbon Brief that it is “concerning to see these low values persisting”, but says that scientists need more time to determine whether this represents a “structural shift” in Antarctic sea ice extent.

Meanwhile, at the Earth’s other pole, Arctic sea ice reached its annual minimum on 12 September, ranking as the joint-10th lowest in the satellite record.

The NSIDC notes that the last 20 years have seen the lowest 20 Arctic sea ice extents in the satellite record.

Dr Lettie Roach, a polar climate scientist at the Alfred Wegener Institute in Germany, tells Carbon Brief that this year’s Antarctic sea ice maximum was “well below average for the season”. She warns that, “after several decades of stable or increasing winter Antarctic sea ice conditions, it is concerning to see these low values persisting”.

She adds: “Compared with the Arctic, it’s less clear how recent changes in Antarctic sea ice are attributable to human-caused warming vs natural variability. We need more years of observations to better understand whether this is truly a structural shift.”

«

unique link to this extract


Projected effects of removing school-entry vaccination requirements on measles transmission in Florida • PNAS

Alice Oveson and Abba Gumel, University of Maryland:

»

Florida’s proposal to remove school vaccine mandates arrives at a moment when measles vaccination coverage in the state has fallen below the level needed to prevent sustained outbreaks. Using a mathematical model, we show that repealing the mandate could trigger the largest measles epidemic in the United States in nearly half a century, with projected pediatric deaths numbering in the hundreds within five years.

We find that children are disproportionately responsible for driving transmission. Adult catch-up vaccination and nonpharmaceutical interventions such as masking and isolation can help, but cannot compensate for steep declines in vaccination coverage. These findings provide quantitative evidence that repealing school vaccine mandates risks making measles endemic in Florida and potentially reigniting transmission across the United States.

«

If you ever wondered whether human progress is a ratchet, we offer you the United States under Donald Trump in his second term as the disproof. Along the same lines: “Trump finalises rules to make cars less fuel efficient.“
unique link to this extract


Sony is skipping CES in 2027 as it focuses more on entertainment • Engadget

Kris Holt:

»

Sony’s press conferences have been a staple of the Consumer Electronics Show for decades, but there won’t be one at the 2027 edition. The company said neither it nor its affiliates plan to show off any products at January’s event.

“We continuously and strategically evaluate our approach to events and communications based on the needs and priorities of our diverse business,” Sony told Bloomberg in a statement, noting that it’s placing greater emphasis on entertainment (including games, anime, films and music), its intellectual property and tech that supports creators. Nikkei was first to report the news of Sony’s exit from CES.

The company didn’t have its own booth at CES 2026, though a prototype of the Afeela, an electric vehicle it was making with Honda, was on the show floor. A couple of months later, Sony Honda Mobility scrapped the EV project and the two companies said they’d review the direction of their joint venture.

«

Easy to forget that it has handed over a big chunk of its TV business to TCL. But is this how CES begins to die?
unique link to this extract


12 new things to expect from Apple this October • MacRumors

Joe Rossignol:

»

October will be an especially busy month for Apple this year, with the company set to release the iPhone Duo, both iOS 27.1 and iOS 27.2, and a new Mac Studio configuration with 512GB of RAM. In addition, up to six more Apple products may be unveiled next month, such as new iPad mini, HomePod mini, and Apple TV 4K models.

[Among the “new things” expected:] • Home hub: An all-new Apple smart home hub featuring Siri AI, a 6-inch to 7-inch square display, an A18 chip or newer for Apple Intelligence, FaceTime, and more. A new operating system will feature clock faces, widgets, and more. There will be a tabletop version with a speaker base and a wall-mounted version.
• homeOS: Apple’s smart home hub is expected to run an all-new operating system that may be named homeOS, according to trademark filings.

«

Long-rumoured, this Home hub, but what is it going to do that an iPad couldn’t?

unique link to this extract


• Why do social networks drive us a little mad?
• Why does angry content seem to dominate what we see?
• How much of a role do algorithms play in affecting what we see and do online?
• What can we do about it?
• Did Facebook have any inkling of what was coming in Myanmar in 2016?

Read Social Warming, my latest book, and find answers – and more.


Errata, corrigenda and ai no corrida: none notified
Start Up No.2750: the trouble with Meta’s Muse, OpenAI admits to more web probes, AI pushing up US health costs, language!, and more


Data from millions of MOTs shows that EVs are more reliable in the long term than fuel-powered cars. CC-licensed photo by gato-gato-gato on Flickr.

You can sign up to receive each day’s Start Up post by email. You’ll need to click a confirmation link, so no spam.

A selection of 10 links for you. Charged up. I’m @charlesarthur on Twitter. On Threads: charles_arthur. On Mastodon: https://newsie.social/@charlesarthur. On Bluesky: @charlesarthur.bsky.social. Observations and links welcome.


Meta keeps apologizing for Muse. Its explanations miss the point entirely • Inc

Jason Aten:

»

Meta built Muse as a dedicated Linux virtual machine in the cloud, gave it memory, storage, and an agent capable of using a browser. Then, it made the whole thing available through an app anyone can use. It’s remarkably capable.

That’s genuinely impressive. Meta deserves credit for taking something that has mostly been used by developers and early adopters and turning it into a product accessible to millions of regular people. In fact, Muse has already been downloaded more than 2.5 million times, according to Sensor Tower data.

The problem is, it’s also kind of a nightmare. It isn’t clear if it’s an actual nightmare, or if it just feels like it’s doing nightmare-ish things.

If you haven’t read my piece about Muse uploading all my private text messages and then hallucinating an explanation, you probably should. The short version, however, is that if you give it Full Disk Access on a Mac, it will do things way beyond what you’ve asked it to do. And I’m a pretty tech-savvy person, and I did not give Muse permission to access my messages, and I never once asked it to perform a task that would have required it to do that. Still, it started sending me push notifications about texts I was receiving from my editor as well as my podcast co-host.

When I asked Muse how it knew what I had been talking about, it told me it could see notification previews from my Mac. When I pushed further, it told me it couldn’t give me “the exact plumbing.” It turns out the robot just made that up. The real answer was much worse.

David Singleton, who leads Meta Superintelligence Labs, later explained that Muse doesn’t monitor notifications on your Mac. Instead, if Messages access is enabled, Muse syncs data from the Messages database. He said Muse had incorrectly explained how the feature worked and apologized: “That’s on us.”

In another case, Singleton responded to another post on Threads from a user concerned that Muse had attempted to hack its Gmail. “The issue was the result of an “off-policy” transcript composition that led to model hallucination,” Singleton responded. “We have shipped a fix for this issue and deployed it to all Muses. We are sorry for the frustration which some users experienced during this time and appreciate the feedback from the community.”

At some point, if you have to go around explaining that you didn’t do a good enough job explaining things, you might have a bigger problem on your hands. Especially if the thing you’re explaining is why it’s totally normal that users are being surprised by the amount of personal information your product is accessing.

«

Think everyone else can find all the bugs in this. Not in any hurry to install this, to be honest.
unique link to this extract


OpenAI bots meddled with US government agencies, including SEC and Census • BBC News

Kali Hays and Lily Jamali:

»

OpenAI has acknowledged that it alerted “dozens” of global institutions that their websites may have been meddled with by its AI bots acting improperly.

AI agents attempted to get information from “governments, universities, public agencies, and other institutions”, including the US Securities and Exchange Commission (SEC), Census Bureau and Education Department, the company said.

The disclosures come days after Australian Prime Minister Anthony Albanese announced that OpenAI agents had breached non-public files on the website of its government-run health care scheme.

Since August, public fears have grown over the potentially serious, even life-threatening, impacts of AI tools falling outside of human control.

OpenAI said that some of the data was accessed by AI agents, essentially bots that are designed and trained to operate somewhat autonomously, which were working to find “authoritative sources of public information”.

But the company noted that some of the bots went beyond that and worked to bypass security measures on websites.
When attempting to get information from the Census Bureau, for instance, AI agents used tools reserved for software developers to access it, the company said.

OpenAI said all of the government data accessed by bots was public. However, it noted that information that its bots accessed from the SEC, which regulates the US stock market and protects investors, was later published by AI agents on another website. OpenAI says this action was not intended.

In other instances that OpenAI disclosed on Friday, its AI agents transferred data when it should not have. Such activity resulted in at least 53 incidents where an OpenAI agent took an image from ChatGPT user activity and transferred it elsewhere.

The company said that in each instance of a user image being used and transferred by an AI agent, the user had opted in to allow OpenAI to train models using their data. Nevertheless, OpenAI admitted: “This is not an appropriate use of this data.”

«

As noted last week, the training data for all these LLMs includes how to hack, so this sort of news isn’t surprising. What is becoming clear is that OpenAI had absolutely no idea what it was unleashing; no way of properly tracing in real time what was happening.
unique link to this extract


BCBSA analysis: how AI coding tools affect healthcare costs • Blue Cross Blue Shield

»

New analysis from the Blue Cross Blue Shield Association (BCBSA) finds that hospital systems are increasingly billing patient hospital stays as more medically complex, driving nearly $1bn in additional healthcare costs in just two years. There is a clear disconnect between coding and treatment — our research shows that coding for care has changed, but there is no evidence of corresponding change in care delivered.

The study raises concerns that widely adopted AI coding tools are contributing to higher healthcare spending, which ultimately puts pressure on premiums and out-of-pocket expenses for families, employers and taxpayers.

More than 60% of hospital systems are now using AI-enabled technologies that can scan lab results and electronic records to identify secondary diagnoses, which could move a patient into a higher-severity, higher-reimbursement billing category. For the analysis, researchers looked at secondary diagnoses like anemia following major bowel surgery.

“If patients are truly sicker, we’d expect to see more treatment,” said Luke Chalker, BCBSA’s senior vice president of product and data science. “For example, we’re seeing significantly more anemia diagnoses at these hospitals without a corresponding increase in transfusions. The disconnect between diagnoses and treatment suggests that AI is identifying more billable conditions, not sicker patients.”

Researchers found secondary diagnoses that shifted claims into a higher-reimbursement category accounted for 70% — roughly $650m — of the increased costs for Blue Cross and Blue Shield (BCBS) companies from 2023 to 2025.

«

Well of course AI is going to be used to upsell the diagnosis on people just in case in a system where charging more is incentivised. Doesn’t sound like a good thing, though.
unique link to this extract


When AI tells a story about your health, is it true? • WSJ

David Shaywitz is chief medical scientist at Lore Health and a lecturer in biomedial informatics at Harvard Medical School:

»

Smart-ring maker Oura is expected to go public this week, touting its promise to transform personal measurements into “trusted, actionable insights” for improving health. It’s a compelling premise, yet it has long struggled to survive contact with biology.

Two recent cardiovascular trials illustrate the point. Novo Nordisk’s ziltivekimab, an experimental drug designed to suppress inflammation, sharply lowered inflammatory biomarkers but didn’t reduce the risk of cardiovascular death, heart attack or stroke. Novartis’s pelacarsen lowered Lp(a), a lipoprotein strongly implicated in heart disease, without reducing cardiovascular events. These results highlight the complexity of biology and the challenge of predicting outcomes from measurements taken many steps upstream.

At first, this seems the sort of problem artificial intelligence could solve. In some domains AI performs spectacularly. AlphaFold predicts three-dimensional protein structure with extraordinary accuracy, drawing on decades of experimental information, strong biological constraints and an answer that can be evaluated directly. “What structure does this protein adopt?” is a more tractable question than “What will happen to this patient if we dose this compound?”

…A continuous glucose monitor worn by a nondiabetic can produce a detailed account of post-meal glucose. But in this setting the measurements are less reliable, responses to the same food can vary substantially, and there is little evidence that minimizing these fluctuations improves long-term health. Wearables like Oura and Whoop (also reportedly planning an IPO) pose a similar problem: They combine heart rate, heart-rate variability, sleep and other signals into proprietary “readiness” or “recovery” scores, generally using unvalidated formulas, with little evidence that following the result improves performance, prevents injury or benefits health.

Generative AI is remarkably good at turning ambiguous, incomplete information into a coherent account. Give it your declining heart-rate variability, shortened sleep, increased mileage and stressful Tuesday, and it can fashion a plausible story connecting them, even when the explanation remains uncertain. As Daniel Kahneman observed, “No one ever made a decision because of a number. They need a story.” Personalized explanations can be seductive because they arise from our own data.

«

But often the stories are made up; chatbots have no intentions so their lying is a side effect of how they are being used.
unique link to this extract


English Vocabulary Test (adaptive) • TakeTest

Emil Kirkegaard:

»

An English vocabulary test of 108 items in two formats: for most you pick the word that matches a given meaning; for the harder ones you pick the two or three words out of five that are synonyms. The words are rare on purpose — this is a test of the top of the vocabulary range, not of everyday English.

Vocabulary is the single best short measure of general intelligence in adults who grew up speaking the language. The items were calibrated on 499 US adults recruited through Prolific in 2023, and your score is reported as an IQ relative to White US adults of your age (vocabulary keeps growing into the 60s, so the same score means less at 70 than at 25). If English is not your native language your score will mostly reflect exposure to it, not intelligence.

«

97th percentile here (26/30) for age v US white males. (The older you are the more words you’re expected to know.) Fun!
unique link to this extract


Hackers hijack AI accounts and servers to fuel new cyber crime boom • Financial Times

Tom Wilson:

»

Illicit access to AI models and computing power is fast becoming the hottest commodity in the cyber criminal underworld, as hackers seek to harness expensive large language models for extortion, warfare and espionage.

John Hultquist, chief analyst for Google Threat Intelligence Group, said the cyber security unit had observed a major increase in so-called LLM-jacking this year, including the sale of stolen login credentials for public AI tools and the theft of computing resources by groups that want to run their own models for free.

“What we are seeing in the underground is a growing economy associated with access to AI,” Hultquist, a 20-year cyber security veteran, told the FT. 

Cheap access to expensive AI gives cyber attackers a financial edge over their targets, who need to use the same AI tools to defend themselves, Hultquist warned.

“The bottom line is all this behaviour gives them a sort of economic or efficiency advantage against us, because they’re going to essentially be able to get their hands on these tokens at a much cheaper rate,” he said.

Marketplaces on the dark web are selling access to AI models from the likes of Anthropic, Google and OpenAI at discounts of up to 97%, Google Threat’s researchers have found. AI subscriptions for the most advanced versions of ChatGPT and Claude can cost as much as $200 per user every month.

Given AI labs monitor for signs of such abuse, some of the sellers even offer “guaranteed access” by committing to provide new credentials at no extra cost if the initial account gets blocked, Hultquist said.

«

unique link to this extract


Siri AI settlement website now live: Apple to pay some iPhone owners • MacRumors

Joe Rossignol:

»

In May, Apple agreed to pay $250m to settle a US class action lawsuit over Siri AI’s delayed launch, and the settlement website is now live.

Apple will pay an estimated $25 per eligible iPhone to eligible customers, who can submit a claim via the settlement website between September 21 and December 21 of this year. The exact payment may be higher or lower than $25 depending on the total number of valid claims submitted and other factors, with the maximum amount set at $95.

Apple denies all of the allegations made in the lawsuit. Apple agreed to the settlement to avoid the costs and risks of a trial.

In June 2024, Apple previewed new Siri capabilities powered by Apple Intelligence, including understanding of a user’s personal context, on-screen awareness, and deeper per-app controls. For example, Apple showed an iPhone user asking Siri about their mother’s flight and lunch reservation plans based on info from the Mail and Messages apps.

Apple advertised those Siri features in product presentations, on its website, in a TV commercial starring actor Bella Ramsey, and elsewhere.

In March 2025, Apple delayed the launch of the personalized version of Siri, leading to the company being hit with a class action lawsuit alleging false advertising.

«

That is pretty rapid turnaround for a class action suit. The US does these things differently. And we now know the value of AI Siri: it’s $25. (Unfortunately this is only for US users. UK users might see a class representative suit gradually edge through our courts.)

unique link to this extract


Massive UK study finds high-mileage electric cars more durable than petrol • Electrek

Jameson Dow:

»

A study of millions of UK vehicles shows that electric cars stay on the road longer than petrol cars, and the gap widens as mileage increases.

With electric cars being a relatively new technology, many people have been skeptical of what their long-term reliability would look like. Despite EVs having fewer moving parts which suggests less opportunity for failure, fear of the new still keeps people worrying.

But electric cars aren’t really that new anymore. The oldest EVs of the modern era have now been on the road for nearly two decades, so we’ve got some data now. And it turns out EVs look pretty good, according to a new study.

The study was conducted using data from millions of annual British MOT tests, the standard test of roadworthiness for cars on British roads. These tests focus on a car’s suspension, brakes, tires, exhaust, and emissions.

It checked how likely cars were to come back for another MOT test – if they didn’t, then that meant the car was no longer on the road (whether it be for an issue with those five categories above, or another issue).

In the beginning of their operational life, there’s little difference between roadworthiness of petrol and electric vehicles. EVs actually experience slightly more problems in the early years of ownership, but that’s because EVs tend to put on more miles early than petrol cars do.

When comparing on a mileage basis, EVs have very similar failure rates in the early years, differing by less than a percentage point. But that changes once you get to higher mileage numbers – past 40,000 miles lifetime.

At that point, petrol cars are less reliable, and the reliability only gets worse over time. By the time a petrol car reaches 120,000 miles, it’s 47% more likely to have failed than an EV (16% failure rate vs. 23.5% failure rate).

«

40,000 miles doesn’t sound like a lot? Given that most insurers offer 10,000 annually as the normal expectation, that’s only four years. But there’s so much more to go wrong with internal combustion engines that the rising failure rate ought not to be surprising.
unique link to this extract


Germany maps out fossil fuel exit, backing EVs, heat pumps • Reuters

Kirsti Knolle:

»

Germany’s cabinet approved a roadmap on Wednesday to phase out coal, oil and gas ​by 2045, reaffirming a climate strategy focused on electrification despite a minister’s call for more flexibility on cars, heating and carbon pricing.

An environment ministry spokesperson said the ​plan would be presented at the United ​Nations General Assembly in New York later on Wednesday.

Germany would be the third country after France ​and the Netherlands to adopt a national roadmap under ​an international effort to move away from fossil fuels, the spokesperson added.

Spiegel magazine earlier on Wednesday reported that, under the ​plan, Germany will examine whether an agreed deadline ​to end coal-fired power generation by 2038 can be brought forward to 2035.

In transport, the plan foresees EU fleet emissions rules to lead to battery-electric cars making up 100% of new passenger car registrations by 2035, Spiegel ​said.

That contrasts ​with demands from some conservatives, including Economy Minister Katherina Reiche, to preserve a larger role ​for combustion-engine vehicles using alternative fuels.

«

Incredible how the Green Party in German, through their overreaction to nuclear power, led to coal burning – about as bad for the atmosphere as you can imagine – continuing far past the necessary date. The UK stopped burning coal for power generation at the end of September 2024.
unique link to this extract


The death of apps has already begun • Web Designer Depot

Noah Davis:

»

We spent the last 15 years installing apps for everything. An app for email. An app for music. An app for banking. An app for editing photos. An app for ordering dinner. An app for booking flights. An app for spreadsheets. An app for taking notes. An app for figuring out which other apps we should install.

AI could make much of that feel ridiculous.

Not because AI is going to magically destroy every software company tomorrow, but because the fundamental idea behind the app—the idea that humans should learn an interface designed around a company’s software—suddenly looks surprisingly old-fashioned. The future might not be 200 better apps. It might be one intelligent interface that uses those 200 apps for you.

And the interesting part is that this isn’t entirely science fiction anymore. Apple is making app actions and data available to Apple Intelligence outside the apps themselves through App Intents. OpenAI has moved external apps directly into ChatGPT, while Google’s Gemini can interact with connected apps to perform tasks. The pieces of the post-app world are quietly being assembled while we’re still arguing about whether the Settings button should be in the top-right corner.

Think about what happens when you want to accomplish something today. You decide what you want to do, figure out which app can do it, open that app, navigate its interface, remember where the right feature lives and enter the information in whatever format the software expects. Then, very often, you repeat the whole process in another app.

We’ve become so accustomed to this that we barely notice how strange it is. Want to organize a vacation? You might bounce between a browser, maps, an airline site, a hotel app, your calendar, email, Notes, a weather service and perhaps a spreadsheet. The human is effectively the API connecting everything together.

AI flips that relationship around. Instead of opening eight pieces of software, imagine saying: “Plan a five-day trip to Tokyo in April. Keep the hotel under $250 a night, avoid overnight flights, put everything on my calendar and make me a packing list based on the forecast.”

That’s not really an app interaction anymore. That’s an intention—and intention may become the most important interface in computing.

«

unique link to this extract


• Why do social networks drive us a little mad?
• Why does angry content seem to dominate what we see?
• How much of a role do algorithms play in affecting what we see and do online?
• What can we do about it?
• Did Facebook have any inkling of what was coming in Myanmar in 2016?

Read Social Warming, my latest book, and find answers – and more.


Errata, corrigenda and ai no corrida: none notified